Get your free personalized podcast brief
We scan new podcasts and send you the top 5 insights daily.
Requiring coding agents to record screen video or capture UI screenshots proving a bug existed and was resolved builds trust before manual evaluation. For backend features without a user interface, generating before-and-after performance metrics serves as objective verification.

Related Insights
Enhance pull requests by using Playwright to automatically screen-record a demonstration of the new feature. This video is then attached to the PR, giving code reviewers immediate visual context of the changes, far beyond what static code can show.
With AI dramatically increasing code velocity, maintenance shifts from stylistic debates to robust verification. Anthropic's approach is to build ~100x more testing infrastructure than is typical, including fixtures from production data and recordings of the AI using the feature it just built.
To trust AI-generated code, Krieger’s team requires pull requests to include visual proof, such as a "full screenshot gallery of the full UI." This allows human reviewers to quickly spot issues in error states or animations that code review alone would miss, tightening the development loop.
As AI generates more code than humans can review, the validation bottleneck emerges. The solution is providing agents with dedicated, sandboxed environments to run tests and verify functionality before a human sees the code, shifting review from process to outcome.

To scale code review with 8x output, teams should codify and check-in their standards—specs, design systems, style guides—into the repository. AI reviewers can then automatically validate new code against this explicit "statement of what good looks like," reducing the burden on human reviewers.
Kun Chen's 'no mistakes' pipeline includes a testing phase where agents run comprehensive end-to-end tests to check for regressions. Crucially, the agent captures and embeds evidence, like screenshots or videos of the working feature, directly into the PR description for easy human verification.
To maintain high velocity with AI coding assistants, Chris Fregly has stopped line-by-line code reviews and traditional unit testing. He now focuses on high-level evaluations and 'correctness harnesses' that continuously run in the background, shifting quality control from process (review) to outcome (performance).

Shift the definition of "done" from "code checked in" to "logged in as the user and verified the feature works as intended." This simple directive forces engineers to engage with the product from a user's perspective, fostering ownership and higher quality work.

Instead of manually reviewing every line of AI-generated code, mandate that the agent provides proof of its work. This can be before-and-after screenshots, screen recordings of the feature in action, or performance metrics. This simplifies review, especially for non-technical managers.

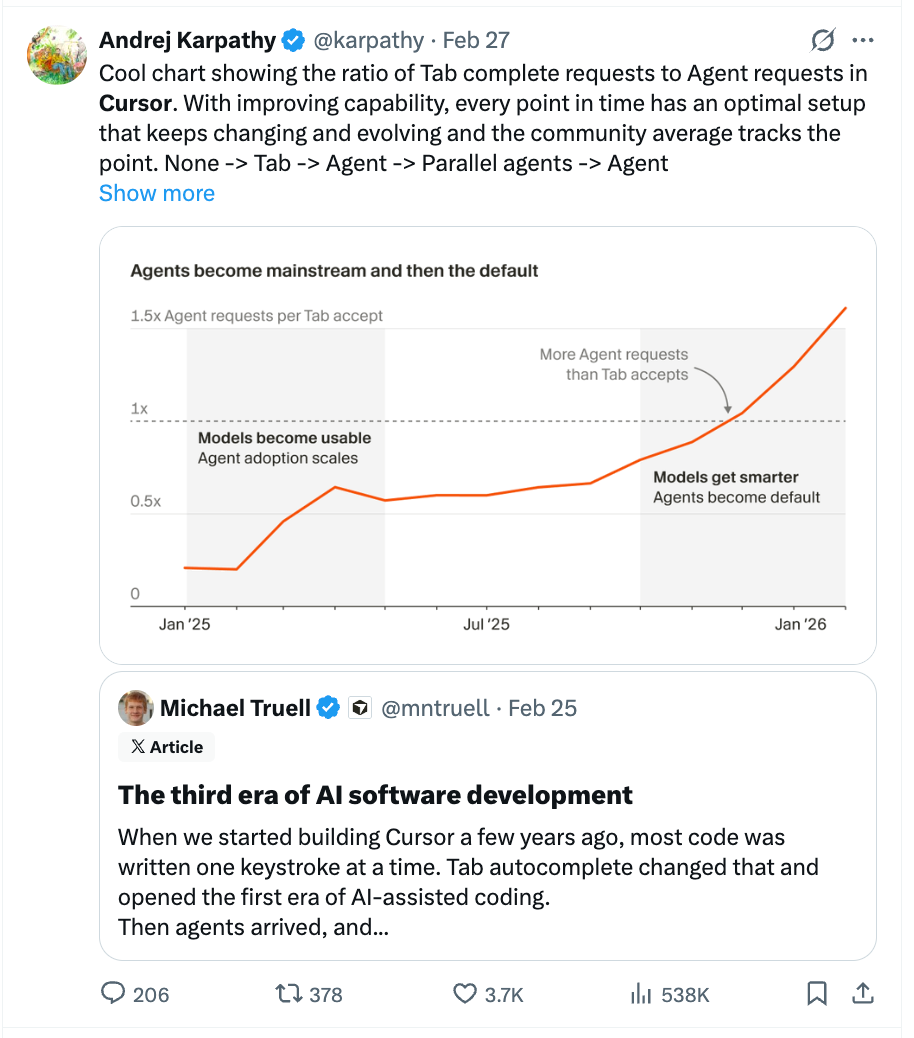
For bug fixes, Cursor's agents can be instructed to first reproduce a bug and create a video of it happening. They then fix it and make a second video showing the same workflow succeeding. This TDD-like "red-green" video proof dramatically increases confidence in the fix.