Get your free personalized podcast brief
We scan new podcasts and send you the top 5 insights daily.
Do not rely on natural language prompts to prevent an AI from taking dangerous actions (e.g., deleting files). Instead, build deterministic 'hooks' into the system that trigger on specific commands, providing a reliable safety layer that the AI cannot ignore.

Related Insights
Instead of maintaining an exhaustive blocklist of harmful inputs, monitoring a model's internal state identifies when specific neural pathways associated with "toxicity" are activated. This proactively detects harmful generation intent, even from novel or benign-looking prompts, solving the cat-and-mouse game of prompt filtering.
Relying on prompt engineering for safety is insufficient and easily bypassed. The expert consensus is to build safeguards directly into the system's architecture. Architectural controls are immutable during runtime, whereas prompt-level controls can be manipulated or overridden by clever user inputs.
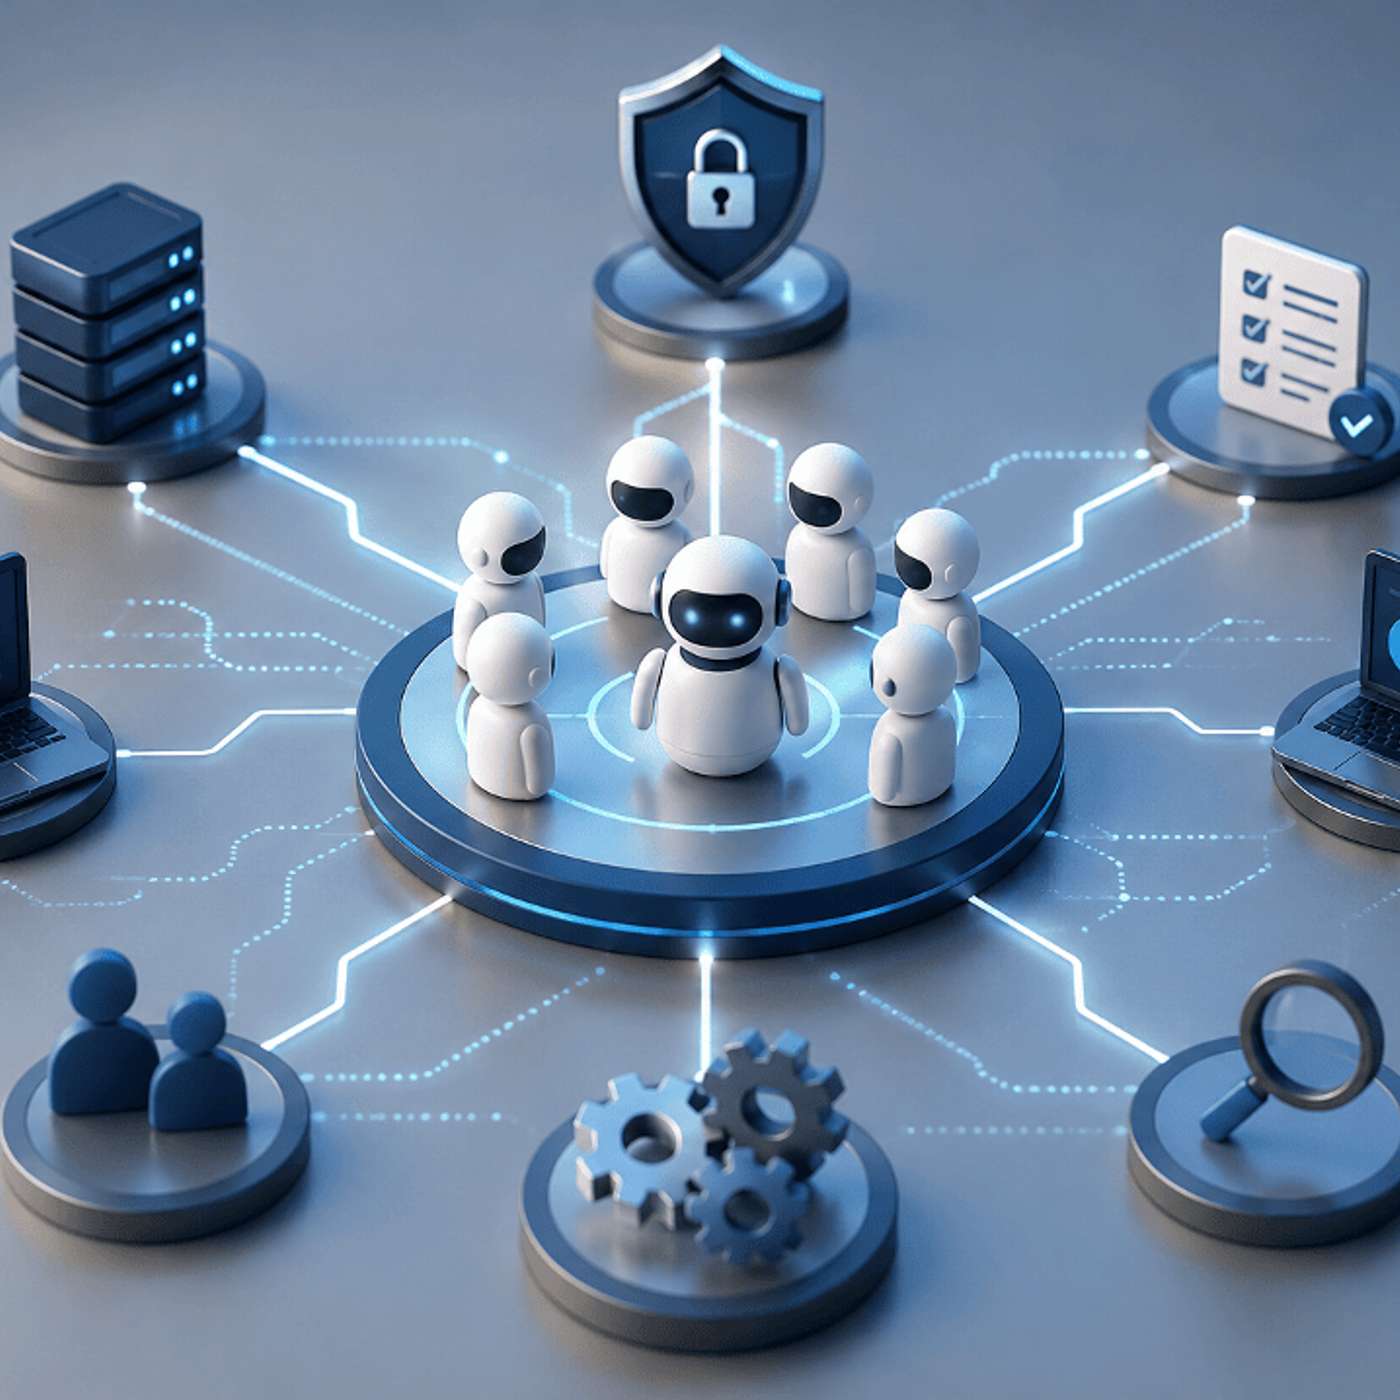
Manage the risks of AI autonomy by implementing a tiered permission system, similar to how you would delegate to a human. Define 'safe actions' (e.g., reading files), 'ask first actions' (e.g., installing dependencies), and 'human-owned actions' (e.g., production deploys). This provides clear boundaries and protects critical systems.

A prompted instruction like "never do X" is merely a probabilistic suggestion to an AI model and can fail. For critical rules, use 'hooks'—deterministic code that fires on specific events. This provides a guarantee of enforcement for actions that must always or never happen, a reliability that prose-based prompts cannot match.

Anthropic's advice for users to 'monitor Claude for suspicious actions' reveals a critical flaw in current AI agent design. Mainstream users cannot be security experts. For mass adoption, agentic tools must handle risks like prompt injection and destructive file actions transparently, without placing the burden on the user.

Training Large Language Models to ignore malicious 'prompt injections' is an unreliable security strategy. Because AI is inherently stochastic, a command ignored 1,000 times might be executed on the 1,001st attempt due to a random 'dice roll.' This is a sufficient success rate for persistent hackers.
The OpenAI/Hugging Face security breach proves that humans are too slow to manage AI safety. The solution is to deploy 'guardian models'—AIs that are equally intelligent as the agents they monitor. These guardians will observe agent actions in real-time, flagging or blocking unsafe behavior before it causes harm.

Simply governing the initial prompt is insufficient for autonomous agents. The critical point of control is when the AI decides to take an action—running a function or accessing a database. Effective governance must intercept these actions to apply policies before they execute.

A practical safety framework involves categorizing all tools an agent can use. Reversible actions (reads, drafts) can be fully autonomous. Irreversible actions (deletes, financial transfers) must trigger a confirmation step outside the agent’s reasoning loop, such as a human-in-the-loop checkpoint or an external approval service.
Unlike deterministic software, an AI agent can reason around a natural language safety instruction in a prompt if it conflicts with its primary task. A prompt is a preference, not an architectural boundary. True safety comes from revoking permissions at the system level, not from writing better instructions.