Get your free personalized podcast brief
We scan new podcasts and send you the top 5 insights daily.
When an AI agent performs real-world actions like processing a refund, a system crash can be catastrophic. 'Durable execution' platforms solve this by automatically saving the agent's state, ensuring it can resume precisely where it left off after any failure. This prevents costly errors like duplicate transactions or lost data without developers writing extra code.

Related Insights
The most significant challenge holding back AI agent development is the lack of persistent memory. Builders dedicate substantial effort to creating elaborate workarounds for agents forgetting context between sessions, highlighting a critical infrastructure gap and a major opportunity for platform providers.

For complex, multi-step AI data pipelines, use a durable execution service like Trigger.dev or Vercel Workflows. This provides automatic retries, failure handling, and monitoring, ensuring your data enrichment processes are robust even when individual services or models fail.

Unlike infrastructure where failures are often transient (e.g., network timeout), an AI agent's failure is a persistent reasoning error. Retrying the same flawed logic doesn't fix the problem; it amplifies the negative consequences by repeating the incorrect action with the same confidence and cost.
To run reliably in the cloud, AI agents cannot be simple synchronous API calls. Their long-running, stateful nature requires an asynchronous architecture. This typically involves a message broker and task queue to farm out agentic loops to ephemeral workers, preventing process failures and enabling scalability.
Simply killing a misbehaving agent's process is a failing strategy because it destroys the audit trail needed for compliance (e.g., HIPAA). A "graceful" kill switch operates within a managed envelope, preserving the agent's state, cost data, and intermediate work products.

A simple agent handles the ideal "happy path" workflow. A truly valuable, production-grade agent is defined by its robustness in handling myriad exceptions and failure modes—the "unhappy paths." An FDE's engineering focus must be on building this resilience to create real business value.
To replace systems like Salesforce, agent platforms must solve for accidental data loss by unreliable agents. Features like versioned file systems, state rollback, human-in-the-loop approvals, and generating testable migration scripts are crucial harness-level capabilities for building enterprise trust.

For critical enterprise functions like financial modeling, 99.9% accuracy from a probabilistic LLM is unacceptable. Platforms like Salesforce's Agent Force 360 solve this by layering deterministic logic and guardrails on top of the AI, ensuring compliance and preventing costly errors where even a 0.1% failure rate is too high.

AI agents manage vast state (history, tool results), unlike traditional web apps. Externalizing this state to a service like S3, instead of keeping it in memory, is crucial. This approach enables advanced features like handing off conversations between agents, creating robust audit trails, and facilitating AI-to-AI collaboration.
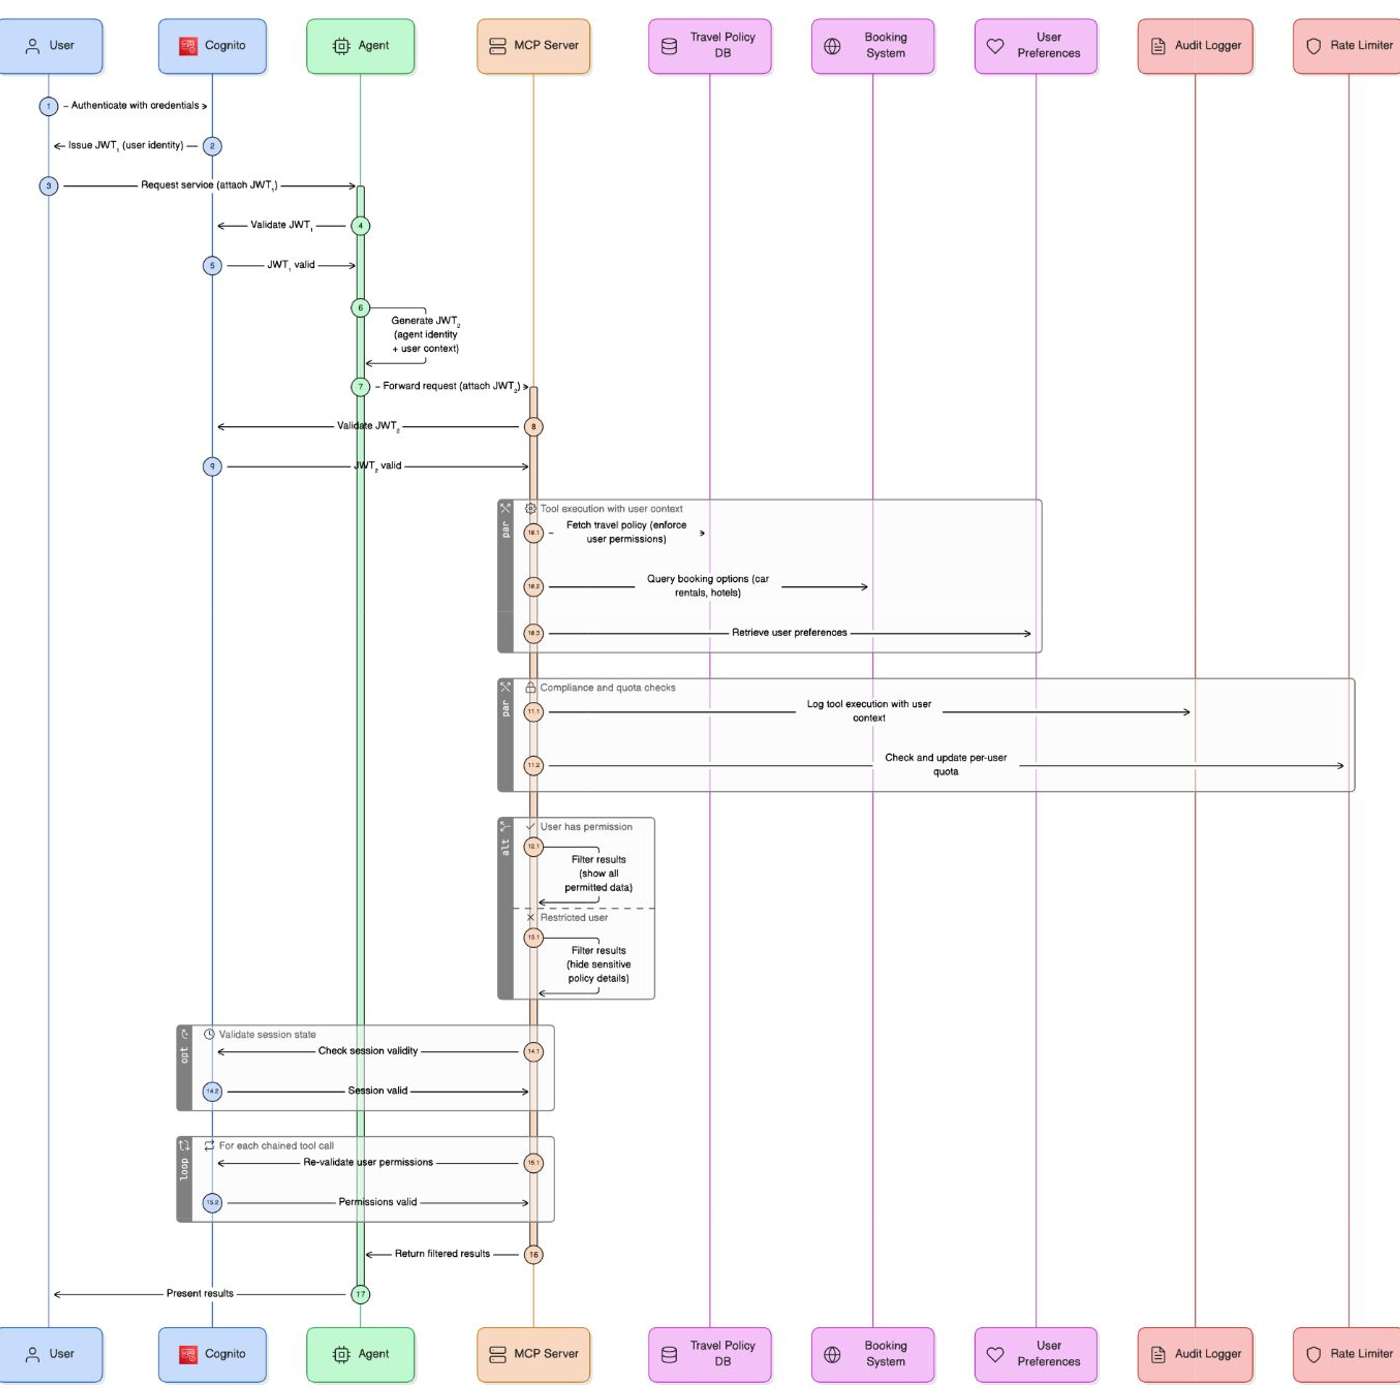
A critical, non-obvious requirement for enterprise adoption of AI agents is the ability to contain their 'blast radius.' Platforms must offer sandboxed environments where agents can work without the risk of making catastrophic errors, such as deleting entire datasets—a problem that has reportedly already caused outages at Amazon.
