Get your free personalized podcast brief
We scan new podcasts and send you the top 5 insights daily.
Aidan Smith says models all talk the same way because they train on similar traces and good rollouts. If algorithms let models learn as much from as little data as humans, they can make inferences in stranger, more creative ways. That could reduce model homogenization.

Related Insights
Prof. Cho argues that modern models already extract most correlations from passive datasets. The next leap in sample efficiency will come from AI agents that can actively choose what data to collect, intentionally making rare, insightful events ("aha moments") more frequent.
Even companies with specialized internal models will use multiple external models. This "neurodiversity" in AI, using models trained on different data, is crucial for generating creative ideas that a single, consolidated model would miss.

Even with vast training data, current AI models are far less sample-efficient than humans. This limits their ability to adapt and learn new skills on the fly. They resemble a perpetual new hire who can access information but lacks the deep, instinctual learning that comes from experience and weight updates.

Instead of building a single, monolithic AI agent that uses a vast, unstructured dataset, a more effective approach is to create multiple small, precise agents. Each agent is trained on a smaller, more controllable dataset specific to its task, which significantly reduces the risk of unpredictable interpretations and hallucinations.

Aidan Smith says models get well calibrated on math and code because those are easy to verify, while broader creativity lags. He thinks the homogenized, fried behavior comes mostly from post-training, though architecture changes can improve generalization. The training objective shapes the spikiness. That is a fixable target.
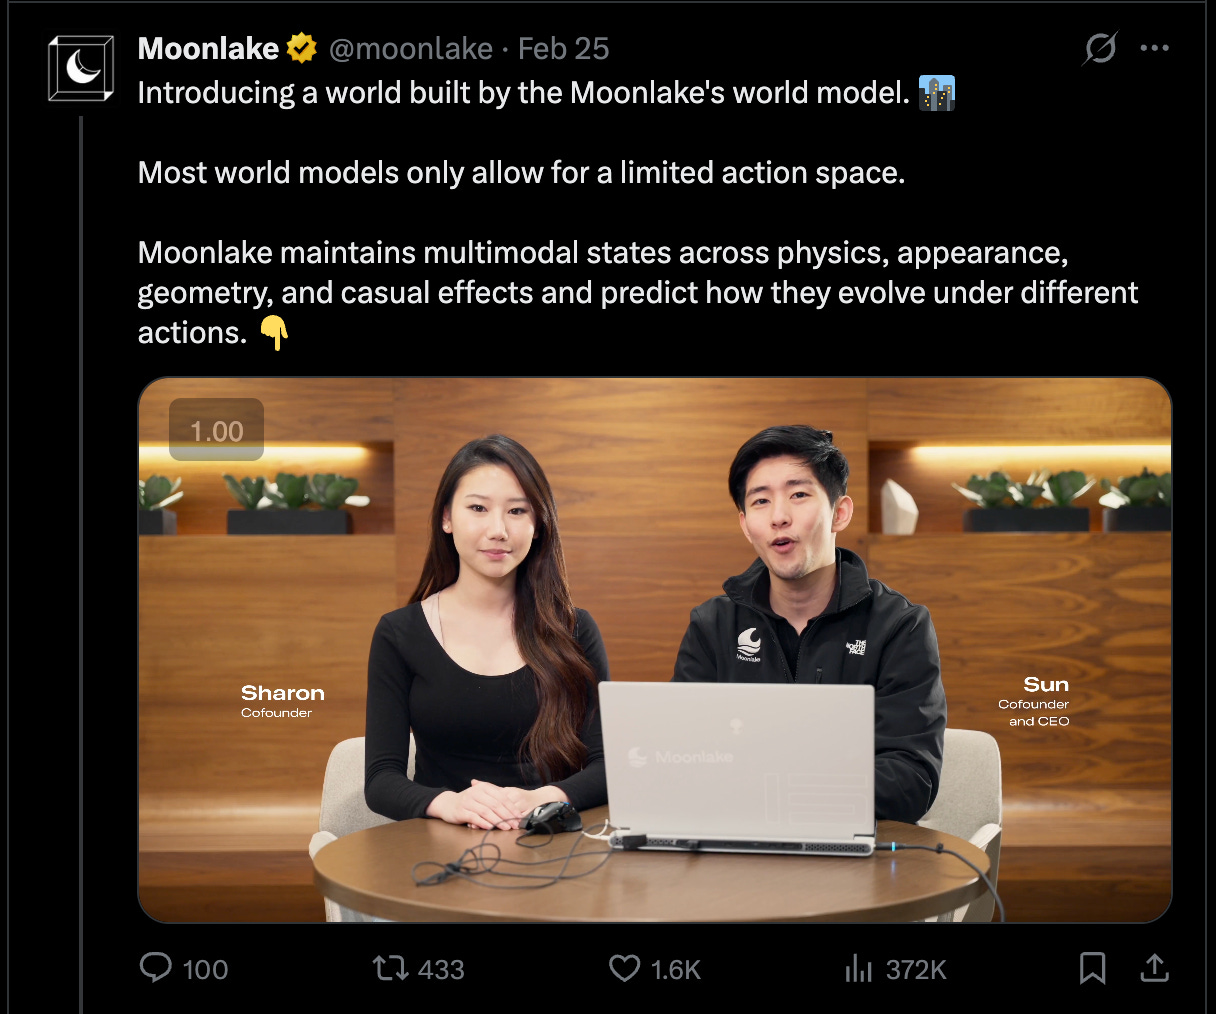
While acknowledging the power of scale, Moonlake argues that incorporating symbolic structure allows models to learn with orders of magnitude less data. This mirrors human cognition, which uses abstracted semantic descriptions rather than processing every pixel.
Static data scraped from the web is becoming less central to AI training. The new frontier is "dynamic data," where models learn through trial-and-error in synthetic environments (like solving math problems), effectively creating their own training material via reinforcement learning.

The most fundamental challenge in AI today is not scale or architecture, but the fact that models generalize dramatically worse than humans. Solving this sample efficiency and robustness problem is the true key to unlocking the next level of AI capabilities and real-world impact.
When determining what data an RL model should consider, resist including every available feature. Instead, observe how experienced human decision-makers reason about the problem. Their simplified mental models reveal the core signals that truly drive outcomes, leading to more stable, faster-learning, and more interpretable AI systems.

A novel training method involves adding an auxiliary task for AI models: predicting the neural activity of a human observing the same data. This "brain-augmented" learning could force the model to adopt more human-like internal representations, improving generalization and alignment beyond what simple labels can provide.