Get your free personalized podcast brief
We scan new podcasts and send you the top 5 insights daily.
Specialized data labeling vendors are growing rapidly from venture-backed AI labs desperate for physical-world sensor data. However, sustaining revenue beyond initial training deals depends on whether enterprise humanoid proofs-of-concept transition into commercial industrial rollouts.

Related Insights
Unlike LLMs that train on the existing internet, robotics lacks a pre-training dataset for the physical world. This forces companies like Encore to build a full-stack solution combining a software platform for data management with human-led operations for data collection, annotation, and even real-time remote robot piloting for exception handling.

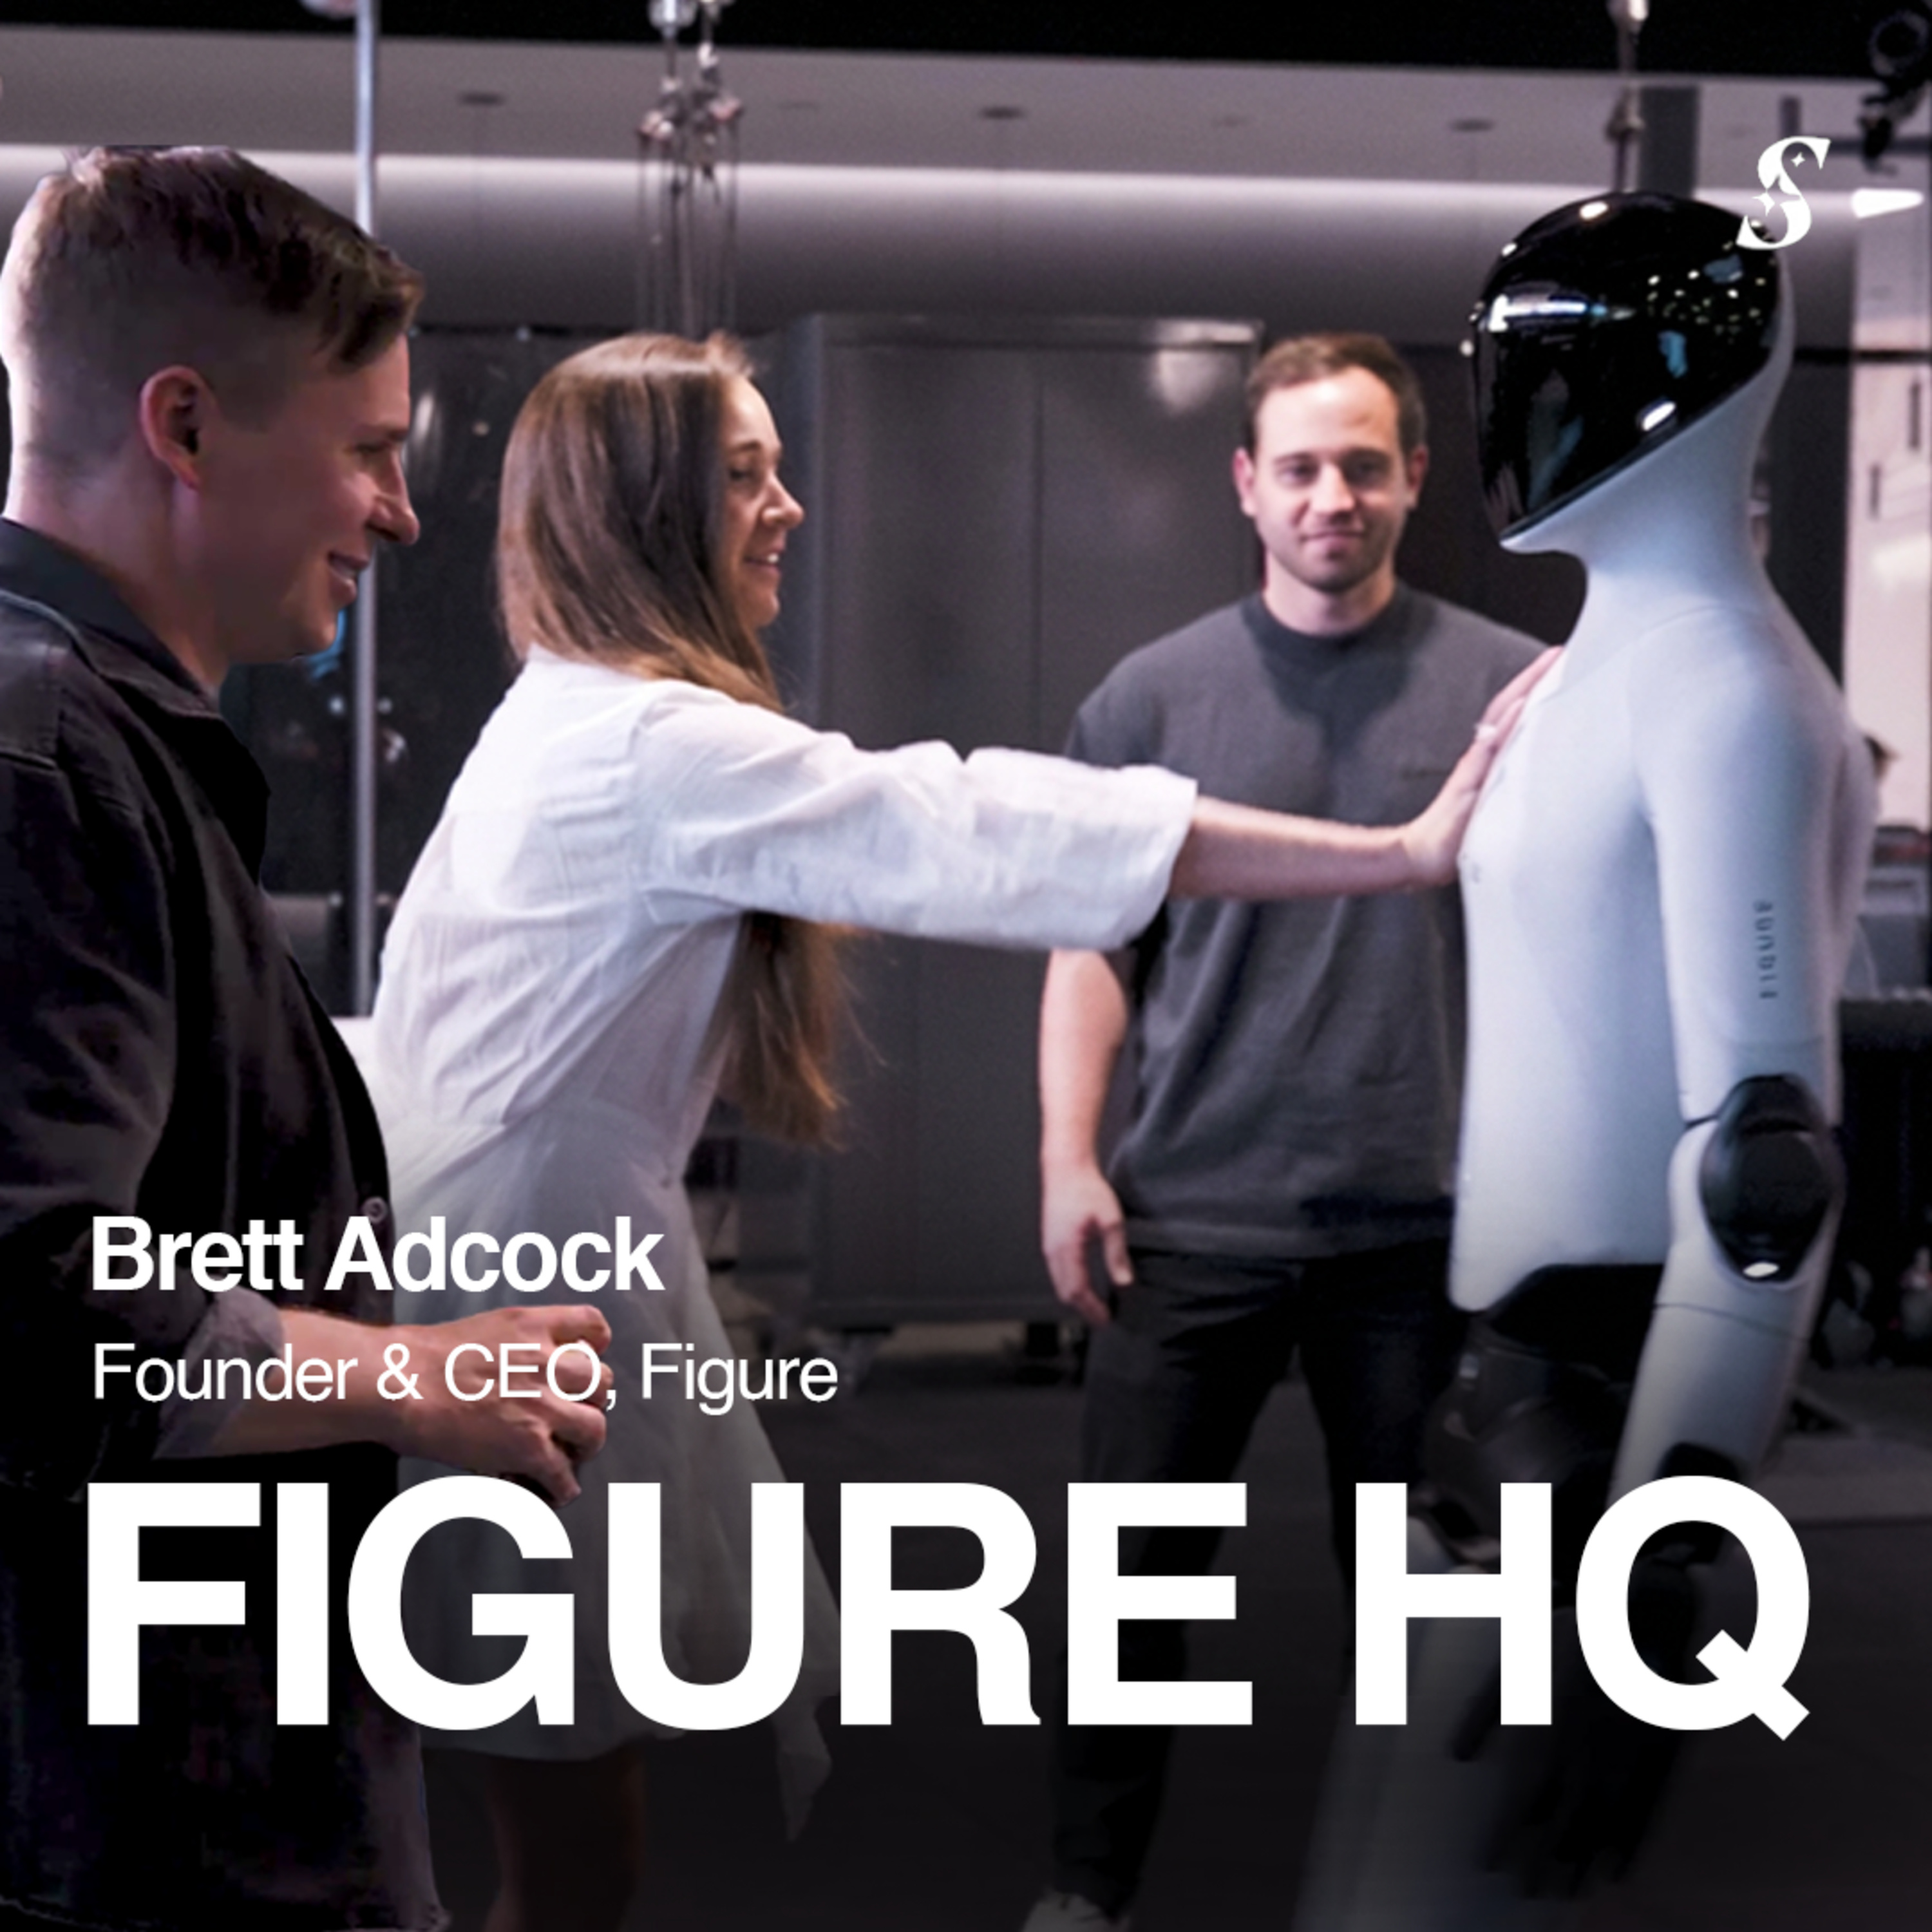
According to Figure's CEO, the company's biggest challenge is no longer hardware reliability but acquiring enormous amounts of diverse, high-quality data. This data is essential for pre-training their Helix AI model to generalize and handle countless real-world scenarios in homes and commercial settings.
Progress in robotics for household tasks is limited by a scarcity of real-world training data, not mechanical engineering. Companies are now deploying capital-intensive "in-field" teams to collect multi-modal data from inside homes, capturing the complexity of mundane human activities to train more capable robots.
The current excitement for consumer humanoid robots mirrors the premature hype cycle of VR in the early 2010s. Robotics experts argue that practical, revenue-generating applications are not in the home but in specific industrial settings like warehouses and factories, where the technology is already commercially viable.

The surge in China's humanoid robot market isn't from consumer or factory adoption. Government-backed centers are buying robots to generate and sell valuable teleoperation training data back to manufacturers, creating a circular R&D ecosystem that fuels the industry's growth.

The humanoid robot industry is stalled by a data paradox: robots need vast amounts of real-world data from factory tasks to become useful, but they cannot be deployed in factories until they are already useful. This catch-22 forces companies to rely on simulated data, slowing the transition from entertainment props to industrial tools.
While data labeling companies show massive revenue growth, their customer base is often limited to a few frontier AI labs. This creates a lopsided market where providers have little leverage, compete on price, and are heavily dependent on a handful of clients, making the ecosystem potentially unstable.
For physical AI, the primary constraint is not the cost of data but its fundamental non-existence. Unlike software AI, you can't advance without deploying robots "in the wild" to capture edge cases—a classic chicken-and-egg problem that simulation alone cannot solve and capital cannot easily buy.
Despite rapid revenue growth selling training and post-training data to foundation model labs, data companies face questionable terminal value. Kanu Gulati points out that once large models learn and synthesize external datasets, they often no longer require ongoing input. Furthermore, open-weight models rapidly distill advances from frontier labs, eroding the proprietary value of that training data for enterprises unless founders continually invent new data categories.

For robotics companies, market dominance hinges on a data flywheel effect. This requires rapidly deploying robots into real-world environments, even at a financial loss, because each unit acts as a data source. A small lead in data collection today translates into a massive competitive advantage tomorrow.