Get your free personalized podcast brief
We scan new podcasts and send you the top 5 insights daily.
Current AI models are still in a "research project phase" and lack the basic diagnostic tools common in mature software. To build reliable systems, AI labs must pause adding features and invest in robust infrastructure—telemetry, logging, step-by-step debugging—that allowed traditional software to scale safely and predictably.

Related Insights
A major bottleneck in AI progress is the gap between research and production. Researchers produce powerful models but often lack software engineering discipline. This results in code that is not portable, extensible, or robust, hindering the transition from a novel idea to a scalable, reliable product.

AI's inherent unpredictability necessitates new engineering practices. Developers must now build robust validation, monitoring, and fallback systems to manage incorrect outputs. Additionally, new security threats like prompt injection and excessive AI permissions demand carefully designed access controls.

AI product quality is highly dependent on infrastructure reliability, which is less stable than traditional cloud services. Jared Palmer's team at Vercel monitored key metrics like 'error-free sessions' in near real-time. This intense, data-driven approach is crucial for building a reliable agentic product, as inference providers frequently drop requests.

The 'move fast and break things' mantra is counterproductive for complex AI development. Tools and philosophies prioritizing correctness and thoughtful architecture over raw speed are better suited for building meaningful, non-trivial AI features that don't become overwhelming to manage.
The massive cost of AI infrastructure makes the traditional startup ethos of "move fast and break things" reckless. Wastage costs are too high and margins for error too low. The new imperative is to "move fast with responsible infrastructure," valuing common sense and iterative development over rapid, wasteful scaling.
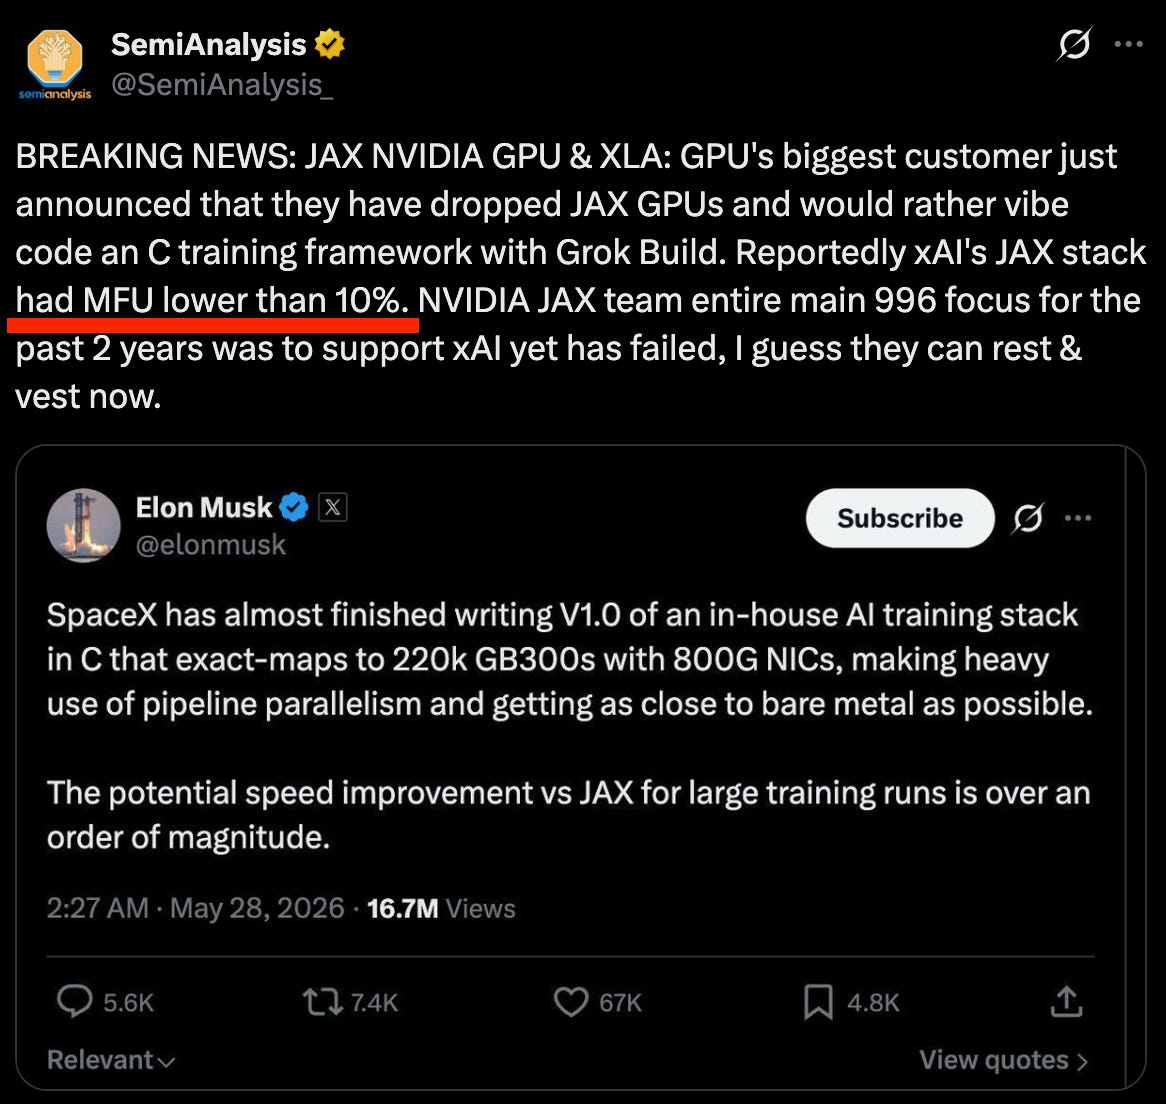
The critical challenge in AI development isn't just improving a model's raw accuracy but building a system that reliably learns from its mistakes. The gap between an 85% accurate prototype and a 99% production-ready system is bridged by an infrastructure that systematically captures and recycles errors into high-quality training data.
Treating AI evaluation as a single, pre-launch check is a mistake. Model behavior drifts due to fine-tuning, infrastructure changes, and shifts in user queries. Production AI systems demand a continuous evaluation pipeline integrated into the deployment lifecycle to catch regressions and ensure ongoing reliability.
OpenAI's Chairman advises against waiting for perfect AI. Instead, companies should treat AI like human staff—fallible but manageable. The key is implementing robust technical and procedural controls to detect and remediate inevitable errors, turning an unsolvable "science problem" into a solvable "engineering problem."
Most AI proofs-of-concept are exciting but brittle, failing to reach production because they can't handle real-world failures. This gap between a cool demo and a reliable service, marked by instability and non-replicable results, is where most projects falter. This is often caused by a lack of scalability and durability in the underlying infrastructure.

Newman's most critical infrastructure for AI-assisted development is a universal logging service for all his apps (front-end, back-end, mobile). When a bug appears, he can tell an AI agent to "debug this," and it can analyze the comprehensive logs to find the root cause without guesswork.
