Get your free personalized podcast brief
We scan new podcasts and send you the top 5 insights daily.
Jev processes requests in milliseconds for a fraction of a cent (e.g., 1,700 emails for 18 cents). This combination of speed and low cost makes it viable for high-volume, real-time applications like instant lead scoring or support ticket routing, which are often prohibitively expensive with large language models.

Related Insights
Analysis of AI spending shows users will pay significantly more for faster model inference (e.g., 6x price for 2x speed), prioritizing interactivity over marginal gains in intelligence. This mirrors how e-commerce conversions are highly sensitive to latency, suggesting speed is a critical, high-value feature for AI products.
Hype suggests JEV is a better, faster ChatGPT, but it's a fundamentally different tool. JEV is designed for machine-to-machine automation, outputting structured decisions and probabilities, not human-like text. It complements, rather than competes with, models like Claude or ChatGPT, and is not for direct human interface.

While often discussed for privacy, running models on-device eliminates API latency and costs. This allows for near-instant, high-volume processing for free, a key advantage over cloud-based AI services.
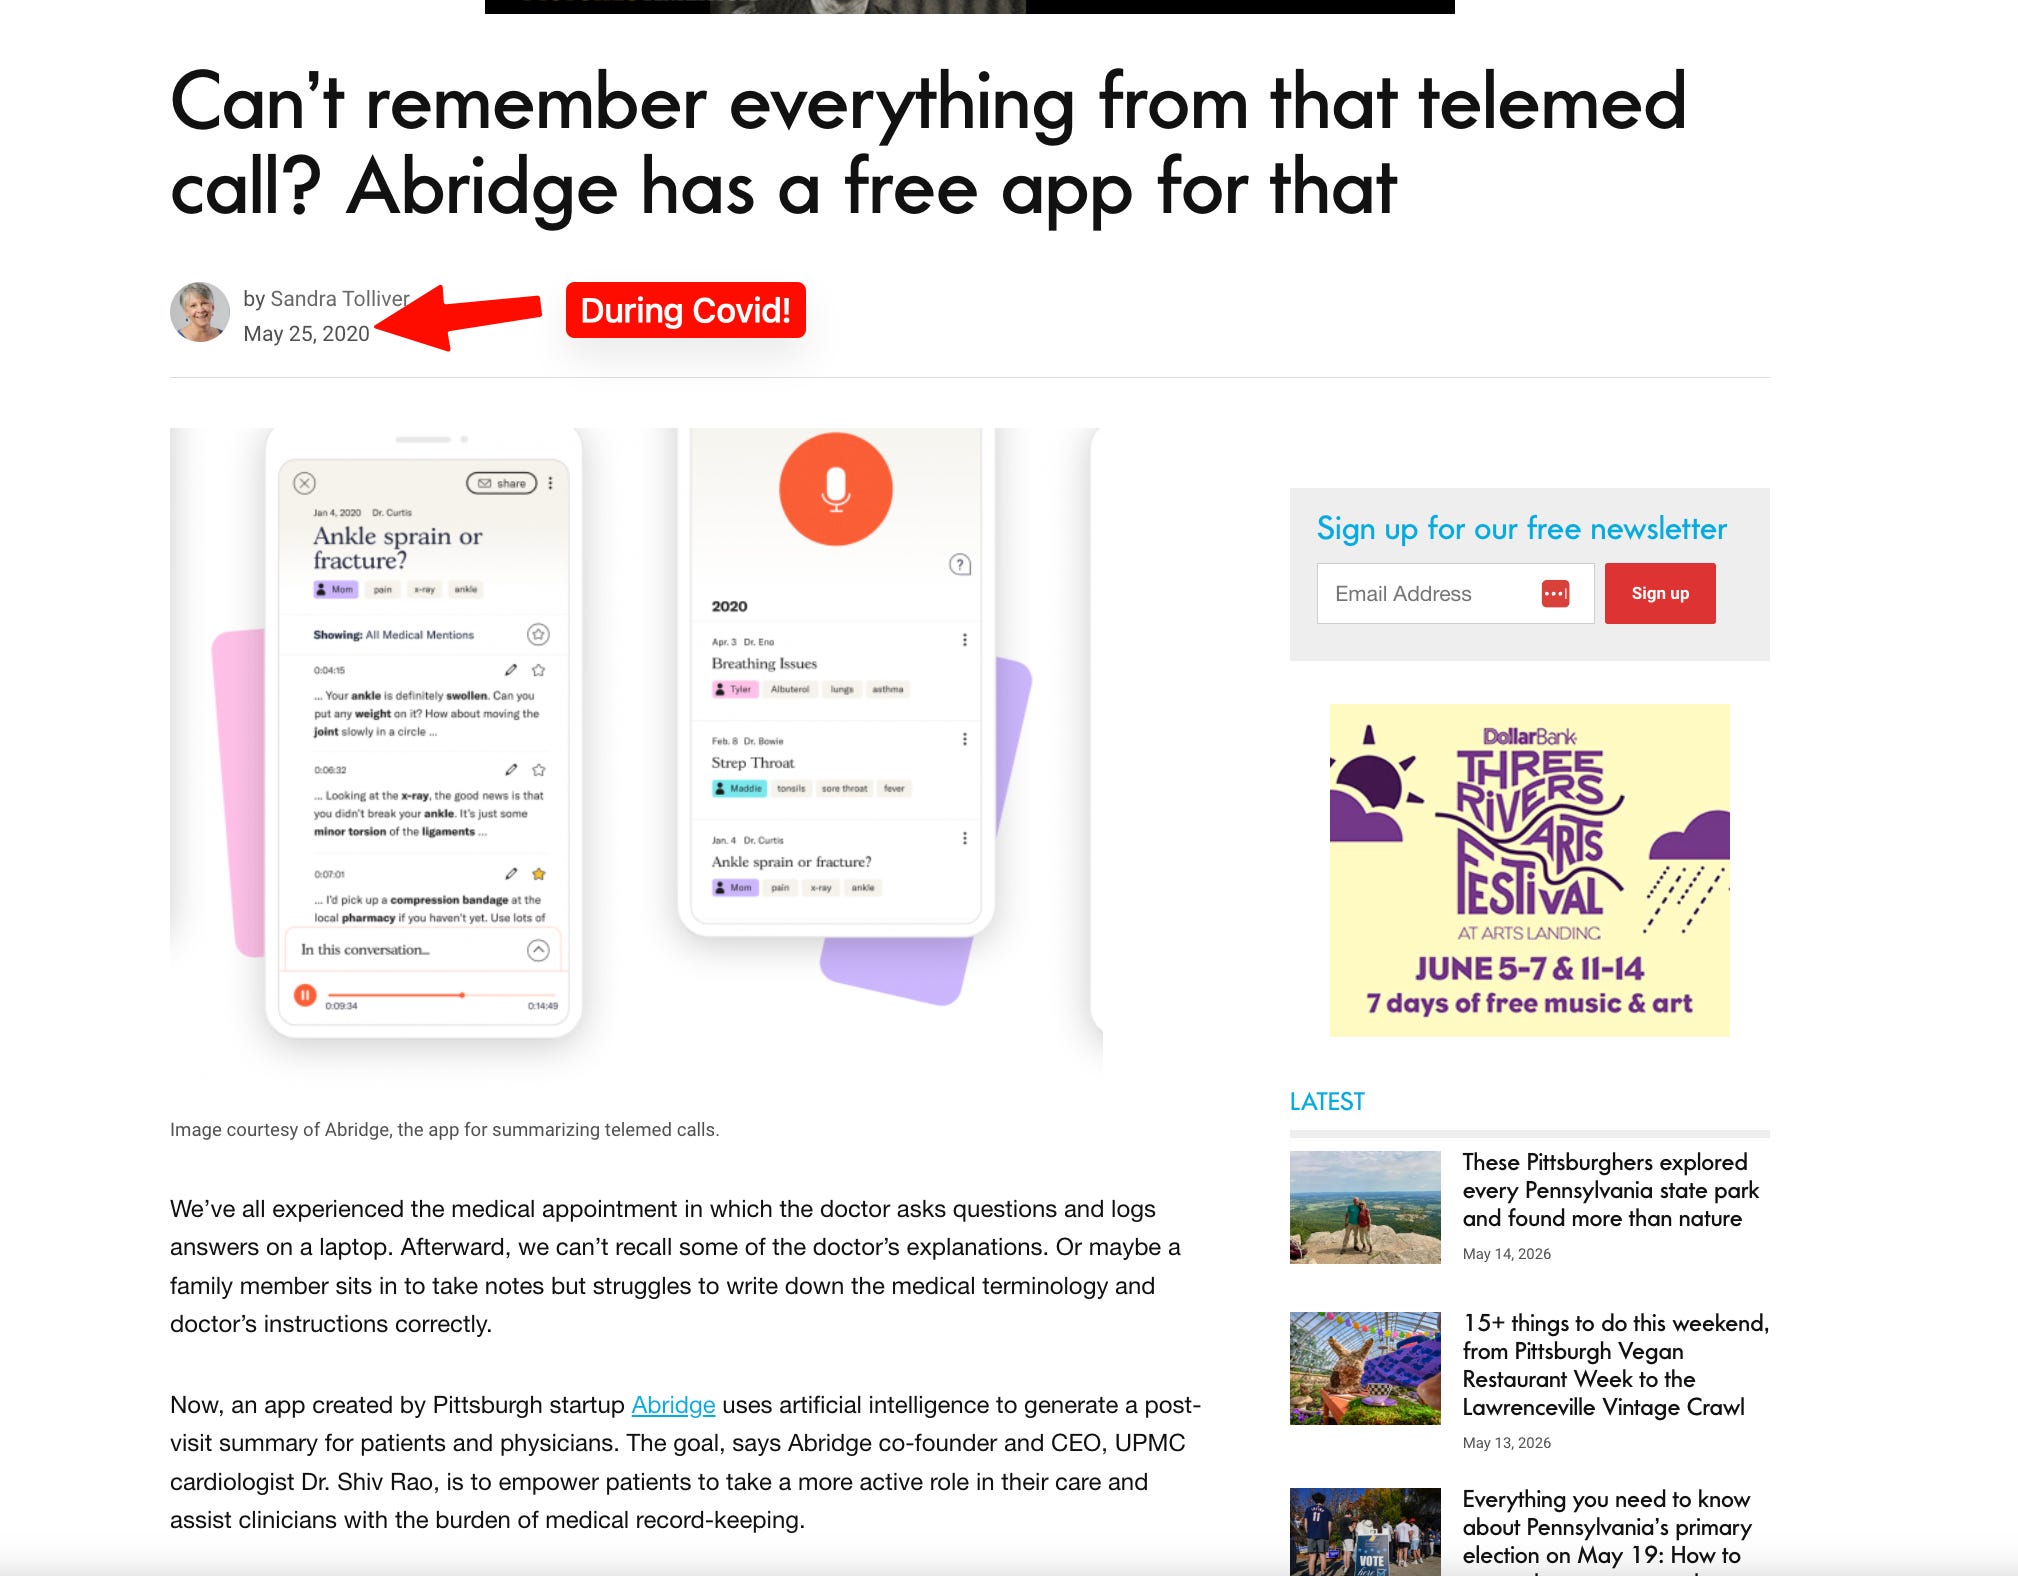
To provide high-quality AI insights in real-time without prohibitive costs, Abridge employs a "fast and slow" thinking approach. It uses a constellation of models, where a cheaper, faster model first triages a situation and then hands off complex tasks to a more powerful, expensive model only when necessary.
Fast and cheap judgment models like JEV can continuously check unstructured content (text, emails) against predefined rules, much like a code linter flags errors for software developers. This enables real-time quality control, style enforcement, and risk detection for all forms of business communication and documentation.

A powerful startup strategy is to identify a business process with high-volume inbound information (e.g., sales leads, support tickets). Jev can be implemented at the front of this queue to instantly classify, prioritize, and route each item, creating immense value through automation and efficiency.
The cost to achieve a specific performance benchmark dropped from $60 per million tokens with GPT-3 in 2021 to just $0.06 with Llama 3.2-3b in 2024. This dramatic cost reduction makes sophisticated AI economically viable for a wider range of enterprise applications, shifting the focus to on-premise solutions.
Parser's AI costs are lower than its server costs. They achieve this by intentionally avoiding the most powerful, expensive LLMs which are often slow and rate-limited. Instead, they find a balance, prioritizing speed and cost-effectiveness to process high volumes affordably.

Companies are building intelligent systems that analyze a user's prompt and automatically route it to the most cost-effective model that can handle the task. This avoids using expensive frontier models for simple requests, with some companies like Coinbase successfully keeping costs flat despite exponential usage growth.

Jev's output isn't a single definitive answer but a probability score for each possible choice (e.g., "80% confident this is a high-priority lead"). This structured, "type-safe" data allows developers to set thresholds and build complex, nuanced business logic directly in their code without parsing text.