Get your free personalized podcast brief
We scan new podcasts and send you the top 5 insights daily.
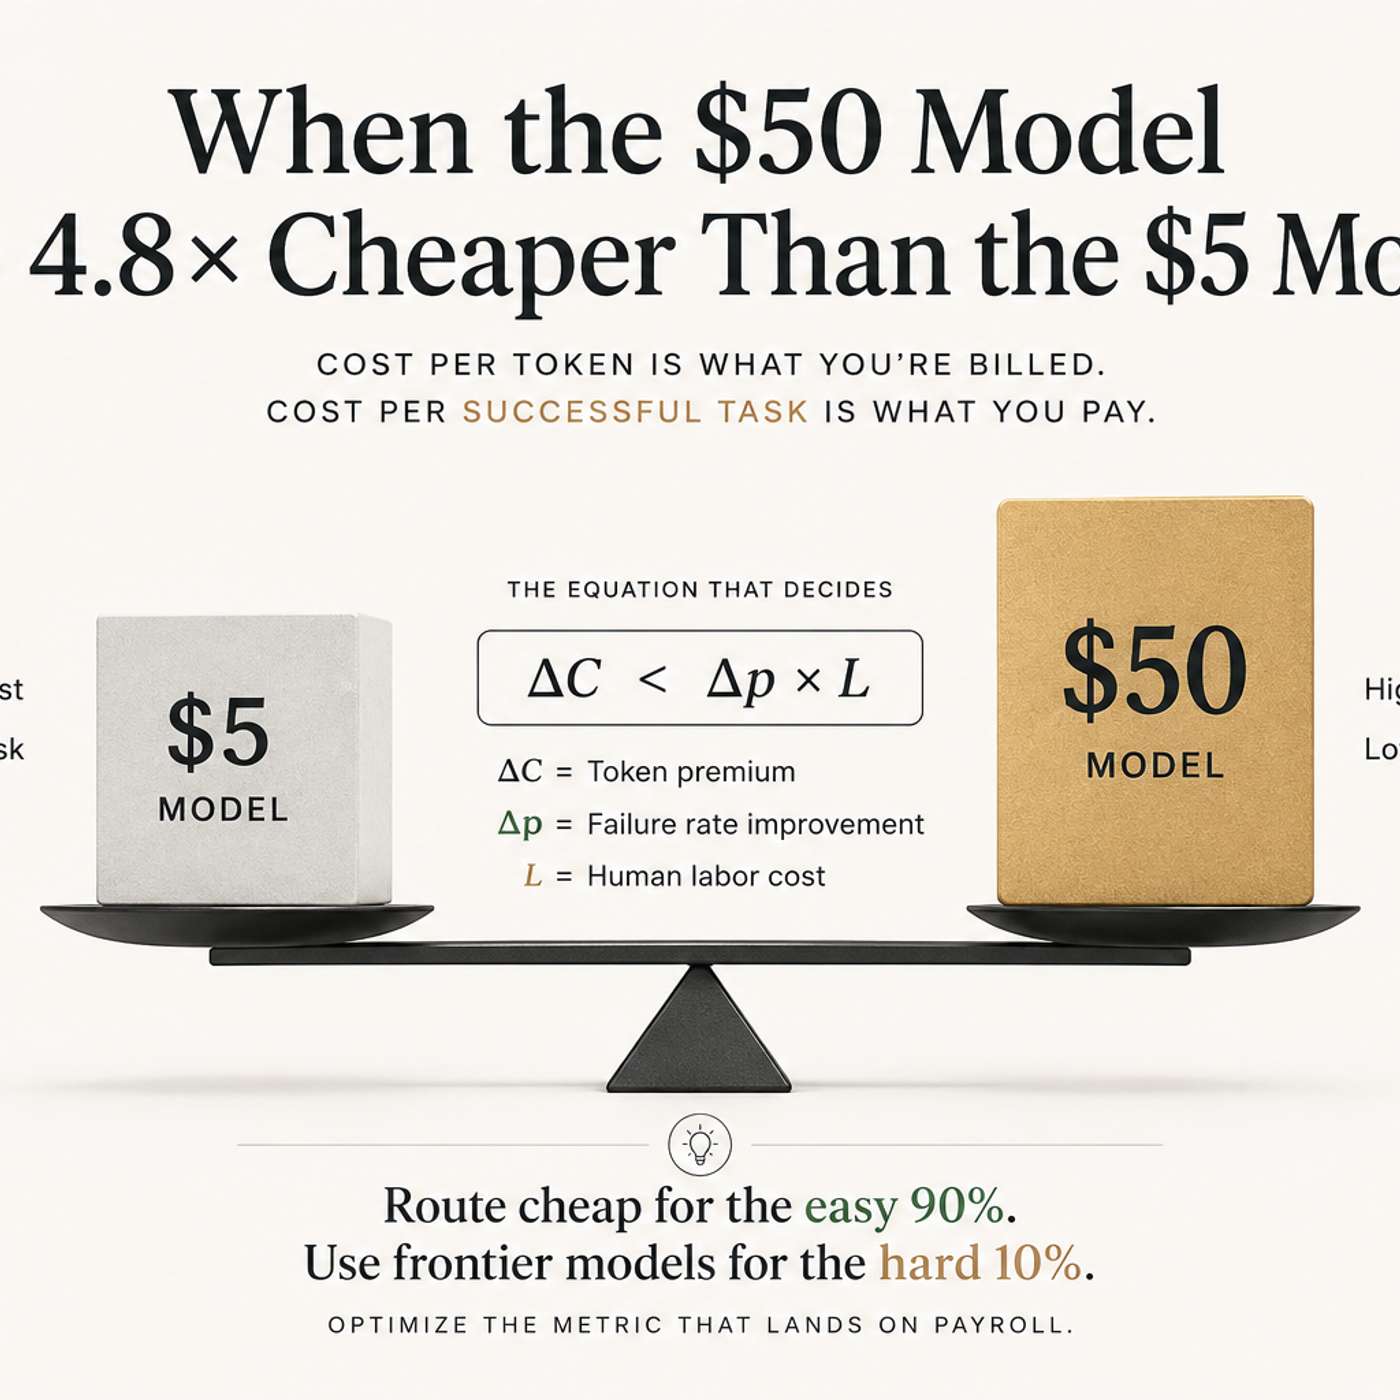
Dane Knecht thinks asking humans to choose a model for every task is silly; intelligent routing should match frontier models to planning and cheaper models to execution. Cloudflare grades people on output and sends usage notices rather than maintaining a token leaderboard. He says people are usually happy to get the notices.

Related Insights
Sophisticated model routers do more than route queries to the cheapest AI model. Palantir's Evolve tool also automatically optimizes prompts for the target model, a dual approach that can reduce token consumption by 60% and overall compute costs by up to 97% for specific tasks.

State-of-the-art flagship models often overcomplicate basic tasks and consume excessive tokens compared to efficient smaller models. Engineers should reserve top-tier models for orchestration and code review while delegating routine knowledge or computation tasks to cheaper alternatives.

To manage AI costs effectively, companies should avoid simply capping token usage, as this kills innovation. A better strategy is to build intelligent routers that assess a task's complexity and dynamically route it to the most appropriate model—powerful models for hard tasks, cheaper ones for simple tasks.

Companies are building intelligent systems that analyze a user's prompt and automatically route it to the most cost-effective model that can handle the task. This avoids using expensive frontier models for simple requests, with some companies like Coinbase successfully keeping costs flat despite exponential usage growth.

A sophisticated gateway that routes queries to different models based on complexity is key to managing AI costs. Simple tasks go to cheap, open-source models, while difficult ones use the frontier. This "expert pattern" allows token usage to rise while keeping costs flat.

The dream of routing a query to the single "best" model for quality is likely an AI-complete problem. In practice, the primary value of model routers is cost optimization: finding the cheapest model on the Pareto frontier that meets a required quality bar, which is a high priority given expensive token costs.
To prevent AI agent usage costs from spiraling, GitHub expects the solution will be intelligent model routing. These systems will automatically select the most efficient and cost-effective AI model for a given task, such as using a cheap model for simple refactoring instead of a powerful, expensive one.
A few months ago, the fear was AI replacing SaaS businesses. Now, the pressing issue is managing massive AI bills. This has elevated 'token economics'—optimizing costs by using different models for different tasks (model routing)—from an advanced technique to a non-negotiable, table-stakes practice for any serious AI implementation.

To control inference costs, companies are implementing model routing systems. They differentiate between expensive tokens from frontier models for complex reasoning and cheaper tokens from fine-tuned open-source models for simpler workflow tasks. This tiered approach optimizes both performance and budget, avoiding "token maxing."
An optimal AI architecture routes tasks to different models based on complexity and risk. Simple, low-stakes work like data extraction should go to the cheapest models. Ambiguous, high-stakes work like system design warrants expensive frontier models, where preventing one engineering mistake justifies the premium token cost.