Get your free personalized podcast brief
We scan new podcasts and send you the top 5 insights daily.
GPUs are ill-suited for generating output tokens because they process models in discrete chunks called "kernels." This method requires constant data transfer to and from external memory, creating a significant bottleneck limited by memory bandwidth, which ultimately slows down real-time inference.

Related Insights
A "roofline analysis" reveals that LLM performance is limited by the slower of two factors: the time it takes to fetch model parameters from memory (memory-bound) or the time it takes to perform matrix multiplications (compute-bound). Optimizing performance requires identifying and addressing the correct bottleneck.
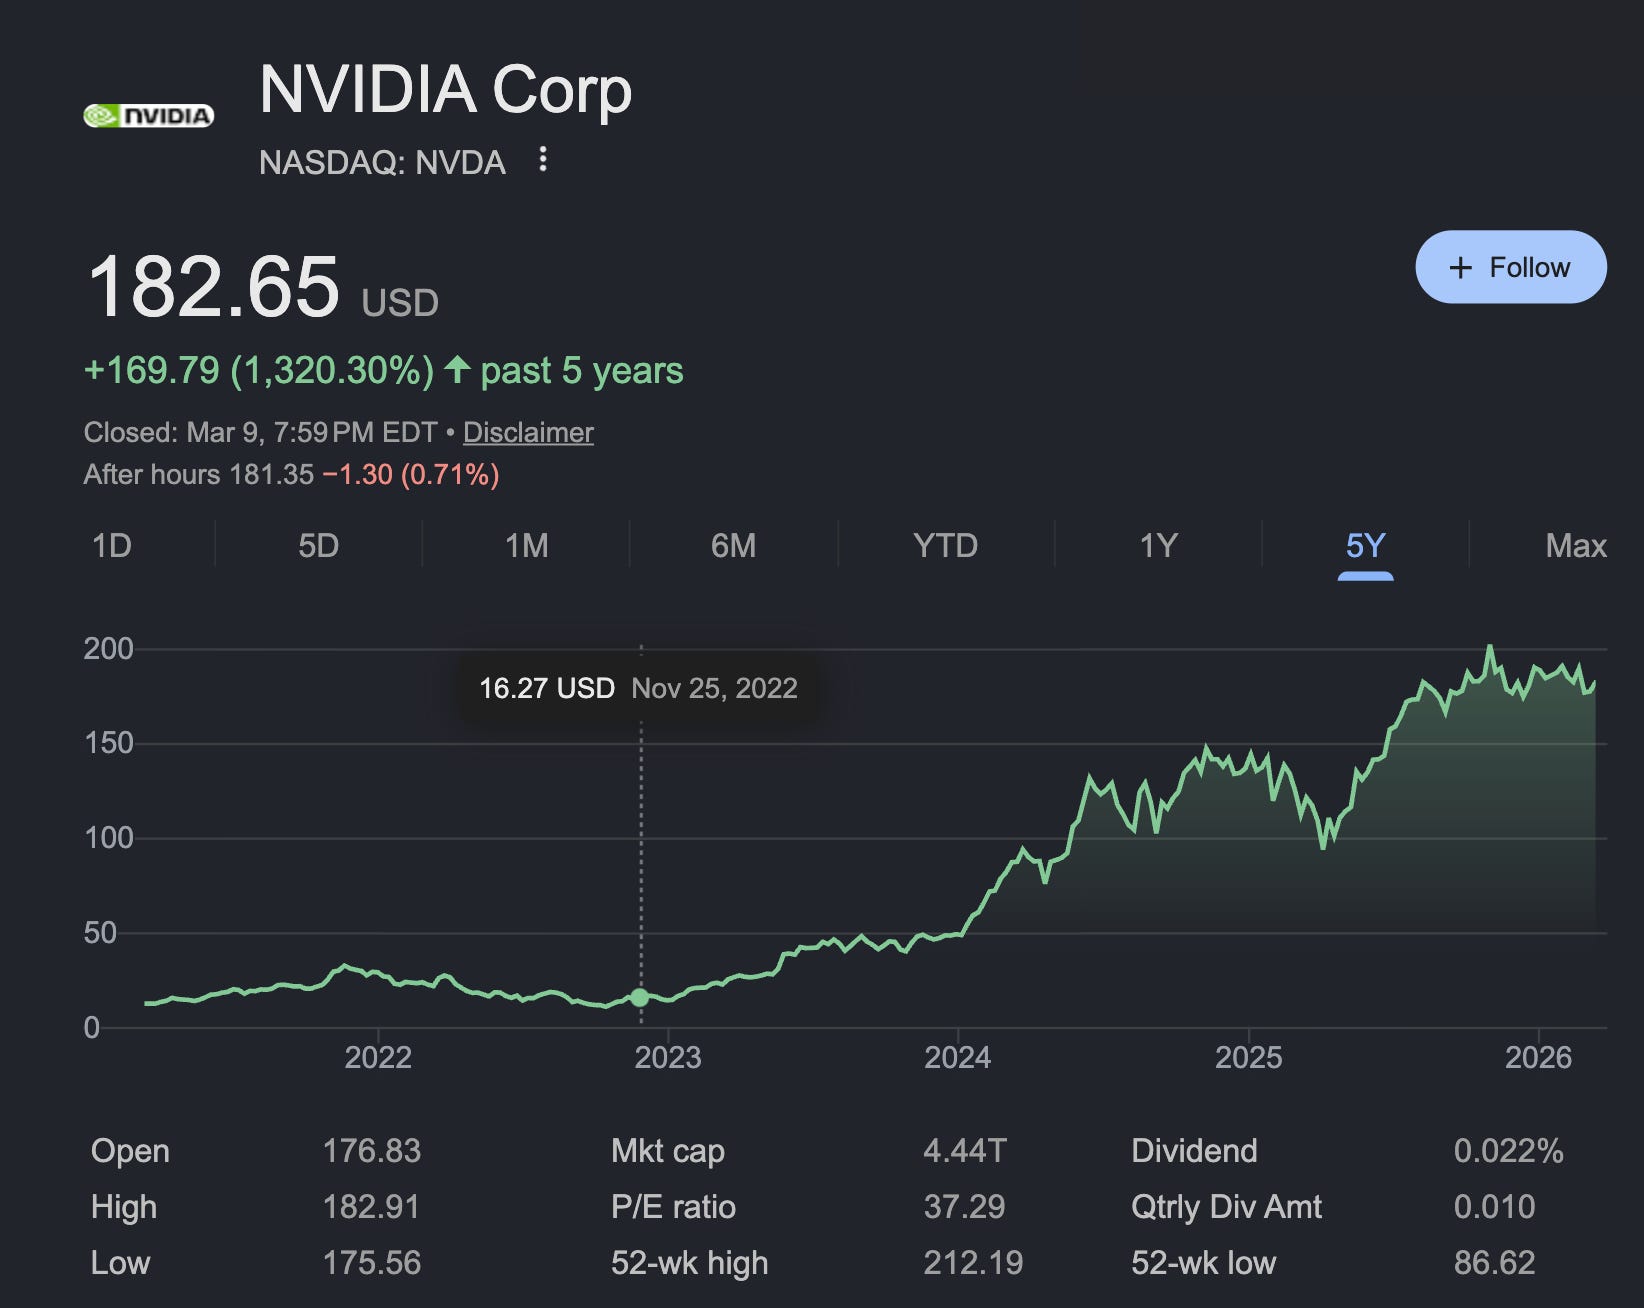
NVIDIA is reportedly considering releasing its next-gen Rubin GPUs with less memory than announced due to supply constraints on high-bandwidth memory (HBM). This suggests fundamental hardware limitations, not just algorithms or data, may soon become the primary bottleneck slowing the pace of AI model growth.

AI workloads are limited by memory bandwidth, not capacity. While commodity DRAM offers more bits per wafer, its bandwidth is over an order of magnitude lower than specialized HBM. This speed difference would starve the GPU's compute cores, making the extra capacity useless and creating a massive performance bottleneck.

Unlike simple classification (one pass), generative AI performs recursive inference. Each new token (word, pixel) requires a full pass through the model, turning a single prompt into a series of demanding computations. This makes inference a major, ongoing driver of GPU demand, rivaling training.

Top inference frameworks separate the prefill stage (ingesting the prompt, often compute-bound) from the decode stage (generating tokens, often memory-bound). This disaggregation allows for specialized hardware pools and scheduling for each phase, boosting overall efficiency and throughput.
The GPU architecture is economically optimized for slow AI inference, offering a very low cost per token. However, this efficiency plummets when speed is required, as the cost and power per token increase exponentially, creating a market for alternative architectures in high-speed applications.

While NVIDIA's GPUs have been the primary AI constraint, the bottleneck is now moving to other essential subsystems. Memory, networking interconnects, and power management are emerging as the next critical choke points, signaling a new wave of investment opportunities in the hardware stack beyond core compute.

For any given hardware, there is a fundamental lower bound on inference latency. This "latency floor" is the time required to load the model's total parameters from memory (e.g., HBM) onto the chip. This process cannot be sped up by reducing batch size or other software tricks.
While many focus on compute metrics like FLOPS, the primary bottleneck for large AI models is memory bandwidth—the speed of loading weights into the GPU. This single metric is a better indicator of real-world performance from one GPU generation to the next than raw compute power.

Unlike traditional computing where inputs were standardized, LLMs handle requests of varying lengths and produce outputs of non-deterministic duration. This unpredictability creates massive scheduling and memory management challenges on GPUs that were not designed for such chaotic, real-time workloads.
