Get your free personalized podcast brief
We scan new podcasts and send you the top 5 insights daily.
The "Interface World Model" treats software interfaces as real-time video. Instead of coding with HTML/CSS, developers can describe UI behavior in natural language. The model generates the interactive pixels directly, enabling rapid prototyping, exploration, and personalization.

Related Insights
AI coding agents enable "vibe coding," where non-engineers like designers can build functional prototypes without deep technical expertise. This accelerates iteration by allowing designers to translate ideas directly into interactive surfaces for testing.
Creating custom "playground" tools for design exploration no longer requires advanced coding. You can simply describe the interface and the controls you want (e.g., "a grid with sliders for rows and opacity") in a natural language prompt to an AI, which will generate a functional tool.
Instead of static mockups, prompt an AI to create a single HTML file containing multiple interactive UI options. This allows designers to quickly test and compare complex elements like animations or hover states, providing a faster and more tangible feedback loop for UI development.
Instead of AI writing code that then gets rendered, future interfaces will be generated directly by diffusion models. This "intention-to-pixel" paradigm allows for hyper-personalized, real-time UIs, effectively making the diffusion model the new front-end.
At OpenAI, the first question is "Can we solve this with the model (tokens) instead of pixels?" This treats the AI as the primary design material, pushing designers to think about interaction and behavior before creating bespoke user interfaces.
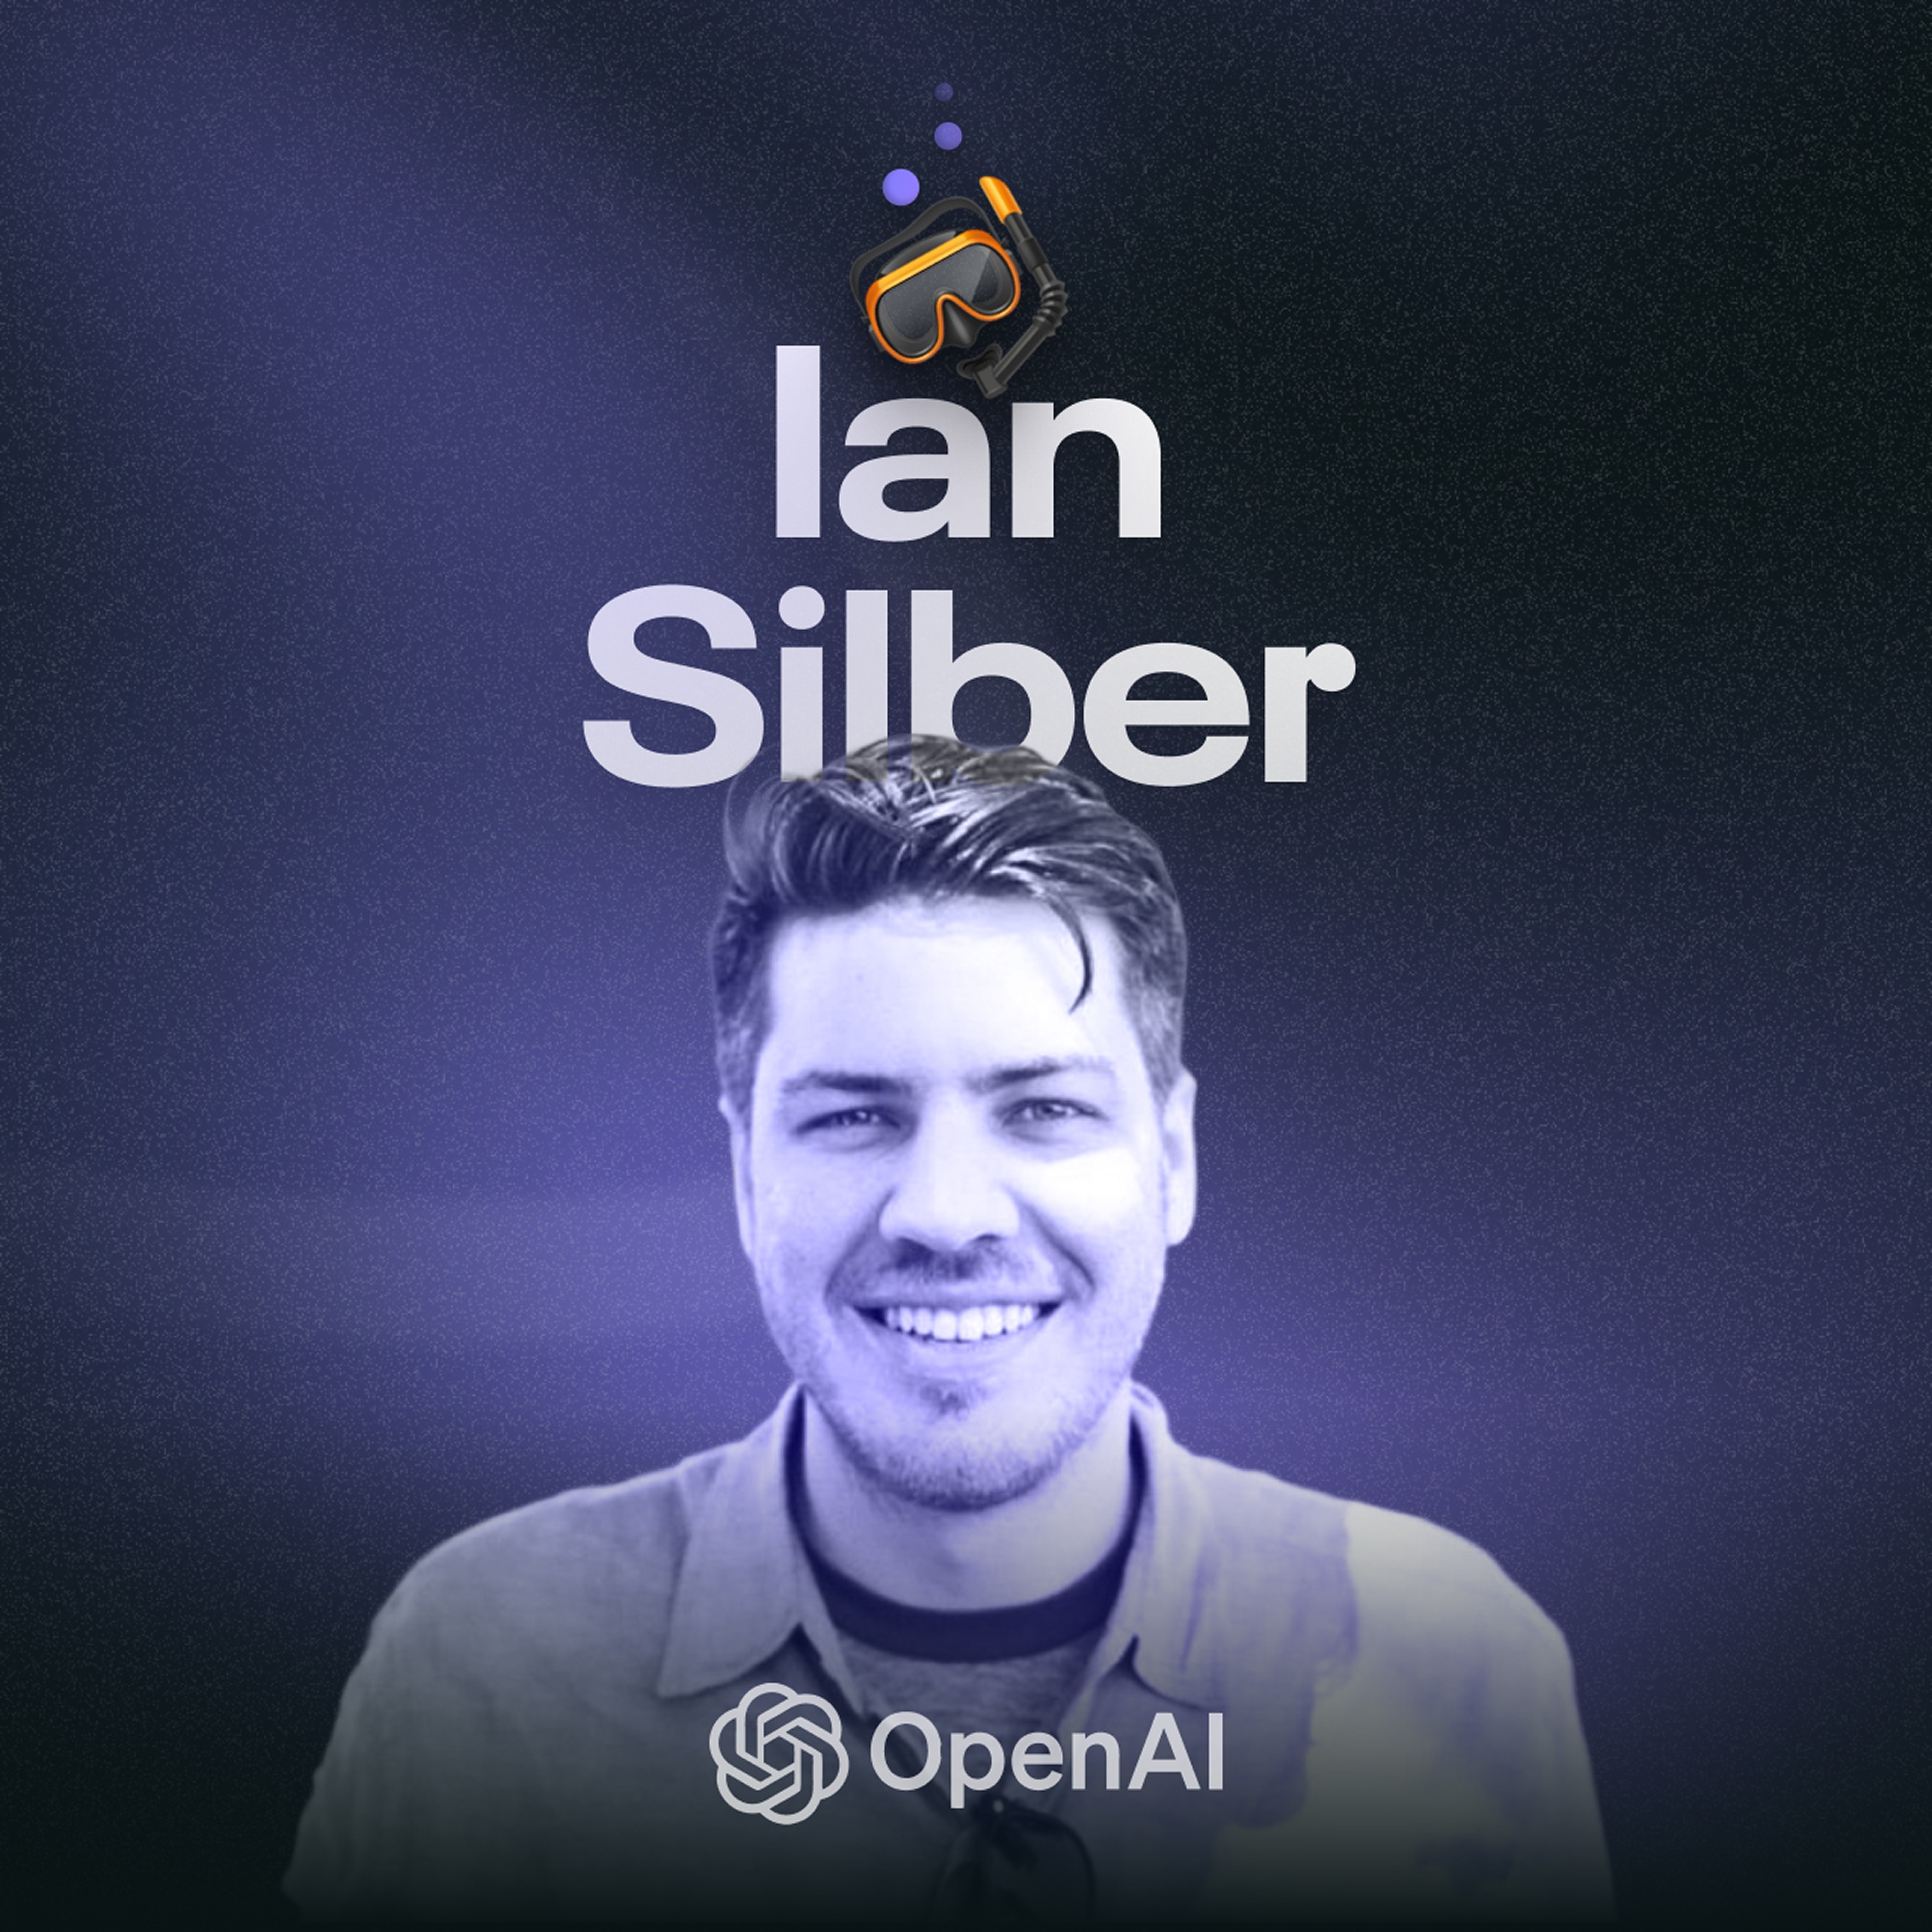
Instead of coding prototypes, OpenAI PMs use AI image generation to rapidly create multiple design mockups from a single screenshot and a text prompt. This offers a much faster iteration loop for exploring UI ideas before any code is written.

A "world model" transcends simple video generation. It is defined by three key capabilities: real-time responsiveness to user input (e.g., mouse clicks), long-horizon consistency over minutes or hours, and interactivity via multiple modalities like keyboard and voice.
OpenAI is developing a "dynamic user interface library" designed so the AI model can interpret and compose UI elements itself. This forward-thinking approach anticipates a future where the model assembles bespoke interfaces for users on the fly.
Traditionally, designers needed to understand code limitations to create feasible UIs. With tools that render a live DOM on the canvas, this is no longer necessary. If a design can be created in the tool, it is, by definition, valid and buildable code.
For generative UI, designers move from defining exact layouts to creating a "skill" that guides the AI. This skill defines a design language, references tokens, and suggests best practices, steering the model's output without over-constraining it.