Get your free personalized podcast brief
We scan new podcasts and send you the top 5 insights daily.
Socher reveals his pioneering 2018 paper on a unified NLP model, which heavily influenced the first GPT paper, was harshly rejected by academic reviewers. They deemed the concept of a single network for multiple tasks 'unfathomable,' halting his team's progress and delaying the field's advancement.

Related Insights
In a 2018 interview, OpenAI's Greg Brockman described their foundational training method: ingesting thousands of books with the sole task of predicting the next word. This simple predictive objective was the key that unlocked complex, generalizable language understanding in their models.
The perception of a 'critically thinking' AI doesn't come from a single, powerful model. It's the result of using multiple levels of LLMs, each with a very specific, targeted task—one for orchestrating, one for actioning, and another for responding. This specificity yields far better results than a generalist approach.
When productionizing GPT-4, OpenAI considered specific applications like writing or coding bots. The now-famous chatbot was chosen not because it was the most obvious idea, but because of leadership's opinionated stance to keep the product general purpose.

The 2017 "Attention Is All You Need" paper, written by eight Google researchers, laid the groundwork for modern LLMs. In a striking example of the innovator's dilemma, every author left Google within a few years to start or join other AI companies, representing a massive failure to retain pivotal talent at a critical juncture.
When OpenAI started, the AI research community measured progress via peer-reviewed papers. OpenAI's contrarian move was to pour millions into GPUs and large-scale engineering aimed at tangible results, a strategy criticized by academics but which ultimately led to their breakthrough.
Prof. Kyunghyun Cho recounts that Yoshua Bengio pushed his lab toward machine translation not just for the task itself, but because it exhibited core AI challenges like handling variable-length sequences and vanishing gradients. Solving translation meant solving these deeper, more general problems.
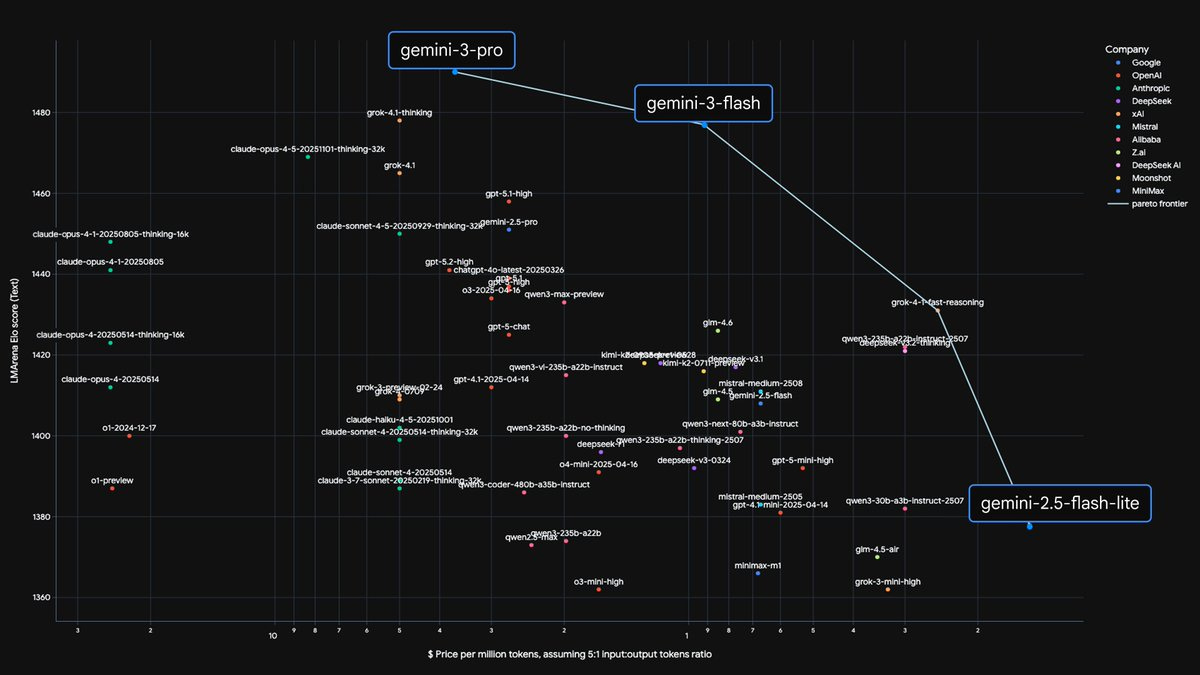
Just as neural networks replaced hand-crafted features, large generalist models are replacing narrow, task-specific ones. Jeff Dean notes the era of unified models is "really upon us." A single, large model that can generalize across domains like math and language is proving more powerful than bespoke solutions for each, a modern take on the "bitter lesson."
Current AIs are trained on the established, consensus-driven scientific literature. The real breakthrough will occur when AI is trained on the 'trash can corpus'—all the ideas and papers that were rejected, laughed at, and dismissed by the orthodoxy. This is where undiscovered alpha lies.

The 2017 introduction of "transformers" revolutionized AI. Instead of being trained on the specific meaning of each word, models began learning the contextual relationships between words. This allowed AI to predict the next word in a sequence without needing a formal dictionary, leading to more generalist capabilities.

Cohere's CEO believes if Google had hidden the Transformer paper, another team would have created it within 18 months. Key ideas were already circulating in the research community, making the discovery a matter of synthesis whose time had come, rather than a singular stroke of genius.