Get your free personalized podcast brief
We scan new podcasts and send you the top 5 insights daily.
Internal scenario testing allows for some statistical uncertainty to narrow broad portfolio risks, but regulatory submissions demand much higher rigor. Generating synthetic control arms or digital twins requires close collaboration with biostatisticians and epidemiologists to statistically mirror real patient distributions.
Related Insights
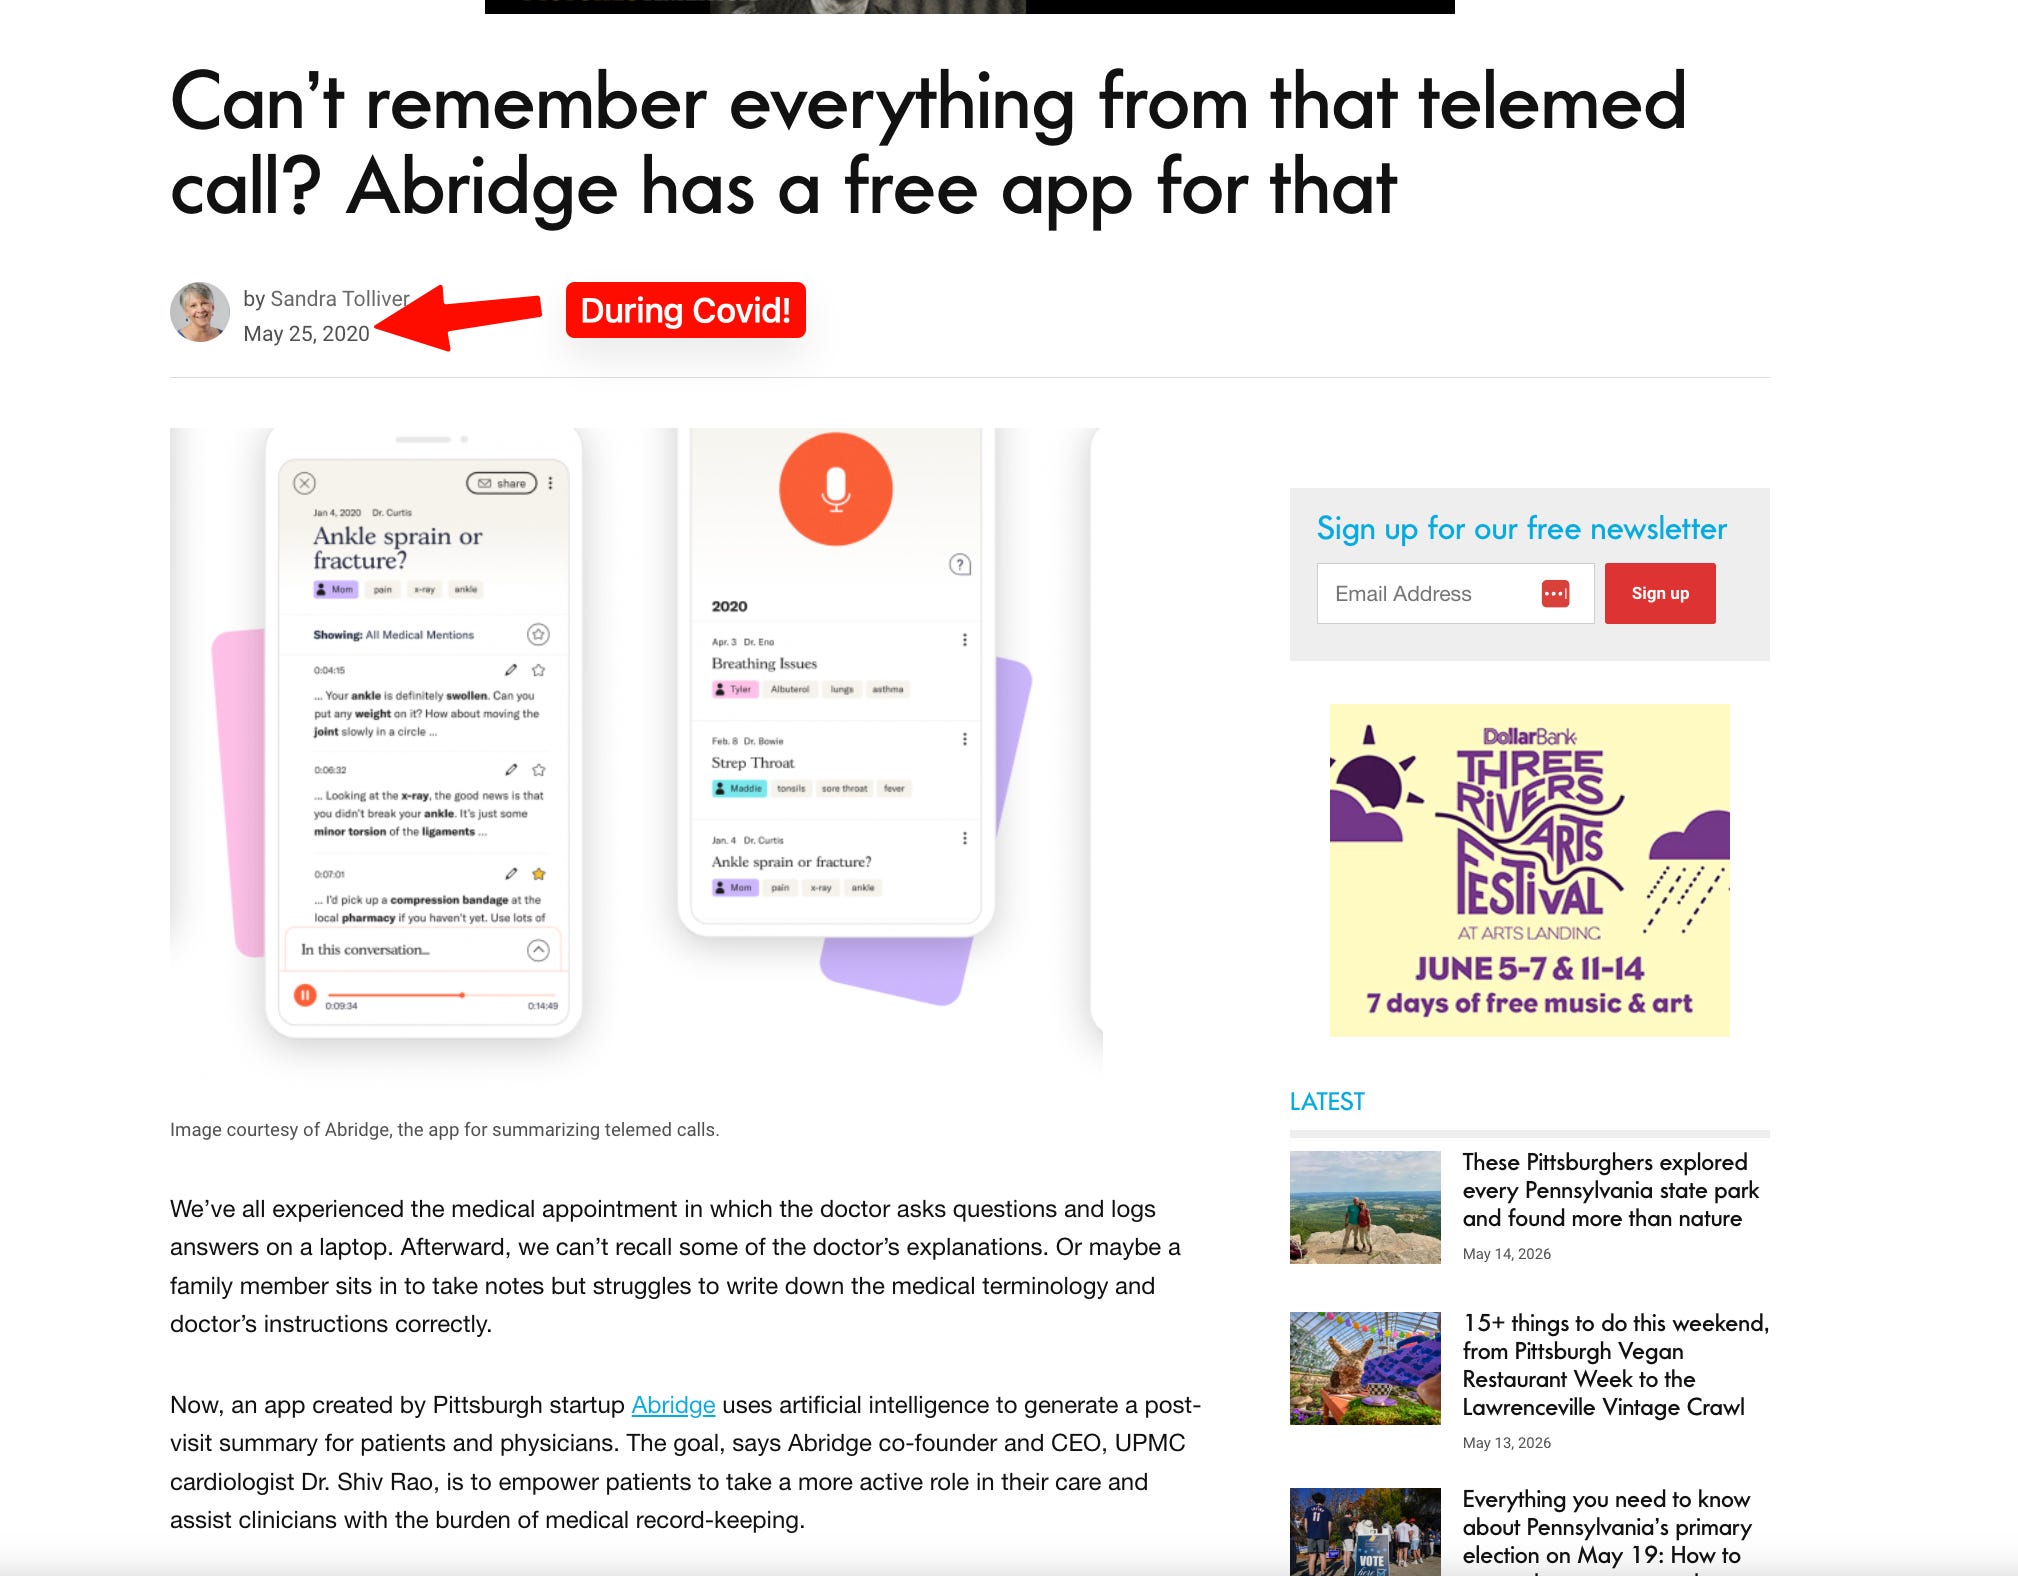
Unlike general enterprise AI where a wrong answer is an inconvenience, errors in healthcare AI can be fatal. This high-stakes environment forces companies like Abridge to adopt extremely rigorous offline evaluation and phased, progressive rollouts, a far more cautious approach than typical "move fast" software development.
For high-stakes decisions like halting a clinical trial, current AI models lack the reproducibility and explainability demanded by regulators. The 'Brakes' platform deliberately avoids AI in its core decision engine, applying it instead to adjacent problems like patient subgroup analysis where the stakes for error are different.
By modeling a complete patient trajectory using multi-omics data, AI could predict how a patient would fare on a placebo or standard care. This would allow for "synthetic" control arms, reducing the ethical and practical challenges of enrolling patients in non-treatment groups.
Unlearn.ai's method for late-phase trials (PROCOVA) is acceptable to regulators because it's designed to statistically correct for any bias in the digital twin model. This ensures the model's inaccuracy doesn't affect the trial's final decision procedure or error rate, a critical feature distinguishing it from simply replacing the control arm.
Many AI vendors, focused on novel algorithms, fail to control for basic statistical principles like Type 1 error (false positives)—a strict requirement from the FDA. 'Cool AI' is useless and dangerous in drug development if it isn't validated by the 'boring' but essential foundations of statistics.
The regulatory pathway for deploying models in manufacturing is not an unknown frontier. It involves a credibility assessment for the model itself, following standards like ASME VNP 40, and established GAMP procedures for validating the data interfaces. This treats the model and its integration as distinct, manageable components with clear guidelines.

It's impossible to generate human data at the scale of in silico experiments. The key is to create highly accurate simulations of human physiology (digital twins) and then validate their predictions with limited, strategic human data. If the model proves reliable, it could drastically accelerate R&D.
Simile's validation method involves collecting extensive data from real people, creating their "digital twins," and then testing if the twins can accurately predict how the real individuals behave in unseen experiments. This grounding in real-world data builds trust in the simulation's outputs.

In high-stakes fields like healthcare, the cost of an AI error is immense. Product leaders must prioritize safety, reliability, and the reproducibility of outcomes. A complete audit trail is non-negotiable, as it enables the reversal of incorrect decisions and ensures accountability.

For critical processes in regulated industries, standard AI model evaluations ("evals") are insufficient. Enterprises like UBS are pushing for research into mathematical proofs to formally verify that AI agents behave correctly across multiple tasks, establishing a much higher standard of trust and safety.
